AI Visibility Metrics: Google, Bing and ChatGPT Reporting Crosswalk
Measure AI visibility without mixing crawler requests, generative impressions, cited URLs, brand mentions, recommendations, referrals, and outcomes.
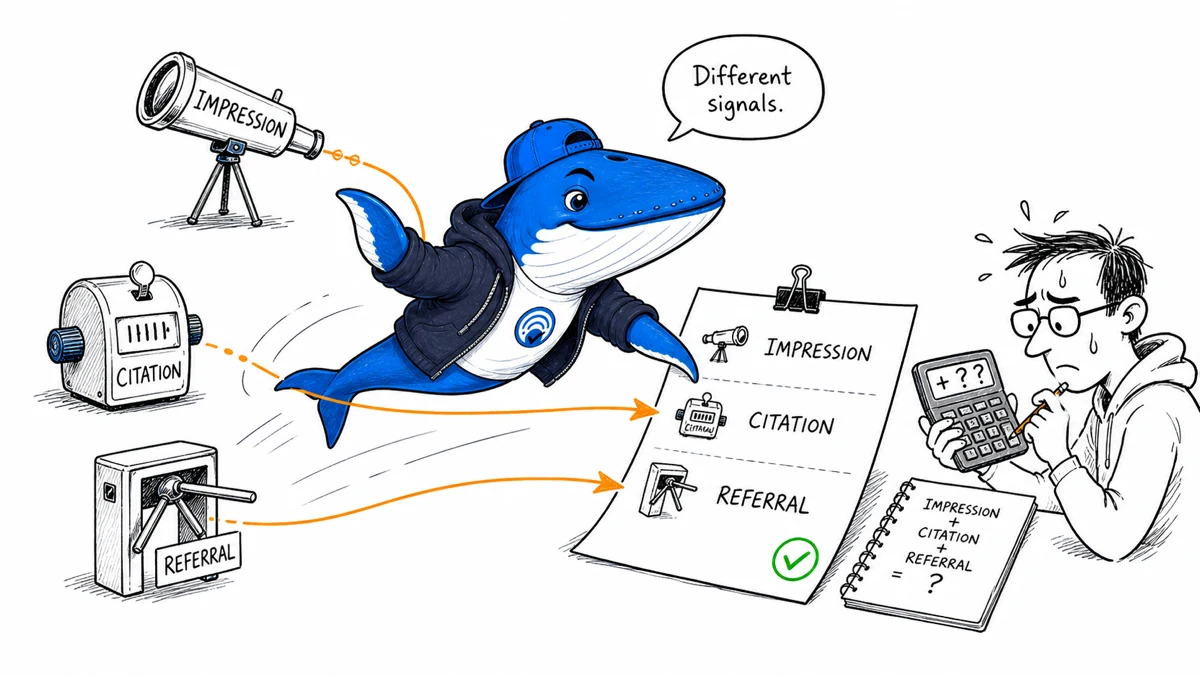
Direct answer: Google, Bing, and ChatGPT expose different parts of AI visibility. Google Search Console reports impressions in supported generative Search features. Bing Webmaster Tools reports aggregated citation activity and grounding-query data. OpenAI documents search-crawler access and tagged referral URLs, but it does not give publishers an equivalent citation dashboard. These numbers should not be combined into one universal “AI visibility score.”
A defensible report separates access, eligibility, appearance, referral, and business outcome. It also preserves the denominator behind every rate. Without that separation, a crawler request can be misreported as a citation, a citation as a recommendation, or a referral session as proof that an optimization caused the result.
Download the AI visibility measurement ledger
Use a five-layer AI visibility model
| Layer | Question | Best available evidence | Does not prove |
|---|---|---|---|
| Access | Could the named crawler request the page? | Verified server or CDN request, response status, bytes, and bot identity | Indexing, retrieval, citation, or training use |
| Eligibility | Could the page be considered for the target surface? | Index state, robots controls, canonical, snippet eligibility, and current platform guidance | That the page appeared |
| Appearance | Was the page shown, cited, mentioned, or recommended? | Platform-native report or a saved answer with resolved source URLs | A click, endorsement, or stable rank |
| Referral | Did a user follow a link to the site? | Landing-session data with preserved source, medium, URL, and consent boundary | Every unseen mention or citation |
| Outcome | What happened after the visit? | Tool use, download, subscription, qualified lead, revenue, or another declared event | That the AI appearance caused the outcome |
The sequence is useful because the layers can move independently. A site can allow a crawler and receive no reported appearances. It can be cited without being recommended. It can receive referrals without appearing in a small monitored prompt set. A report should preserve those zeros rather than hiding them inside one score.
Name the event before calculating a rate
A recent practitioner discussion described many cited pages but only a handful of brand mentions. That is a useful measurement question, not an industry benchmark. The post does not provide a complete answer export, prompt denominator, observation window, or matched referral data.
- Crawler request
- A named bot requested a URL. This is access evidence, not an appearance.
- Generative impression
- A platform counted an eligible link under its own display rules. This is not necessarily a citation count.
- Cited URL
- A saved answer or native report linked to a specific page as a source.
- Brand mention
- The answer named the entity, with or without a linked source.
- Recommendation
- The answer positively selected the entity for the user’s stated need. A neutral mention does not qualify.
- Referral session
- A browser arrival was attributed to the AI platform by the site’s measurement system.
These events can occur in different combinations. An answer can cite a publisher’s page without naming the publisher, mention a brand without linking it, or recommend a product while citing a third-party review. Store one field for each event instead of deriving all of them from the presence of a URL.
What should “share of answer” mean?
Share of answer is not a standardized cross-platform metric. If a tool or report uses the phrase, require the numerator, denominator, surface, sample, and observation window before comparing the number. The closest official platform-specific metric in this area is Bing’s Citation Share, which Bing defines for a particular grounding query as the percentage of citations attributed to a site out of all citations shown for that query.
| Metric | Example calculation | Safe interpretation | Main limit |
|---|---|---|---|
| Bing Citation Share | Site citations ÷ all citations for the grounding query | Relative citation presence inside Bing’s reported citation space for that query | Not market share, ranking, traffic, or a quality score |
| Observed citation rate | Monitored answers citing the site ÷ eligible monitored answers | How often the site was cited in the declared test sample | Depends on prompts, geography, account state, time, and monitoring method |
| Observed recommendation rate | Answers recommending the entity ÷ eligible monitored answers | How often the entity was recommended in the declared sample | A recommendation can appear without a citation or click |
| Citation-to-referral rate | Identifiable referral sessions ÷ observed cited answers | A bounded relationship between two captured datasets | Most publishers cannot observe every answer shown to every user |
Calling any of these “share of answer” without the formula makes the result impossible to reproduce. It also encourages false comparisons between a platform-native aggregate and a vendor’s monitored prompt sample.
Google, Bing, and ChatGPT reporting crosswalk
Google Search Console
Google’s Generative AI performance report isolates impressions from supported generative AI features in Search, currently including AI Overviews and AI Mode. The report can be grouped by page, country, device, and date. Google says the data is already included in the broader Web performance totals, so adding the two totals would double count the same observations.
An impression is not a citation count or a visit. Google applies its Search Console impression rules to these features. The report does not expose prompts or a dedicated recommendation metric. Use it to identify visible canonical pages and trends, then use the Generative AI report guide to preserve filters, aggregation, preliminary-data state, and known anomalies.
Bing Webmaster Tools
Bing AI Performance reports aggregated citation activity across supported Microsoft and partner AI experiences. It includes cited pages and grouped grounding queries; Bing also documents preview views for intents, topics, Citation Share, and period comparison. Bing explicitly says the page view reflects citation activity rather than ranking, authority, importance, or the role a page played in one answer.
Grounding queries are grouped phrases, not full user prompts. The data is sampled and summarized, so totals can differ across views and filters. Preserve the exported table, active filter, selected date range, and the documentation date next to any conclusion.
ChatGPT
OpenAI says public pages can appear in ChatGPT search and that OAI-SearchBot access is needed for content to be included in summaries and snippets. OpenAI also says referral URLs include utm_source=chatgpt.com. Those controls support an access check and a referral segment; they do not expose every answer, citation, prompt, or unseen zero in a publisher dashboard.
Keep OAI-SearchBot search discovery separate from GPTBot’s potential training use. A robots decision is a policy observation, not evidence that ChatGPT retrieved or cited the page.
Use the downloadable measurement ledger
The CSV template records one observation per row. It includes the platform and surface, geography, account and client state, prompt or query identifier, canonical page, evidence layer, appearance type, citation and recommendation labels, referral and outcome fields, denominator scope, source export, evidence file, and notes.
- Freeze the observation contract. Record the surface, account state, location, device or client, date range, prompt set, repetition count, and eligibility rule before collecting results.
- Keep raw and derived fields separate. A saved answer, platform export, and analytics session are observations. A rate or interpretation is derived from those observations.
- Preserve zeros. Record eligible prompts with no citation, cited answers with no visit, and referral sessions with no monitored appearance.
- Resolve source URLs. Save the final destination after redirects and map duplicates to the canonical page without discarding the original URL.
- Write the denominator in words. “Twenty eligible prompts, desktop web, signed out, United States, run three times during one week” is more useful than “60 checks.”
- Add a limit before the recommendation. State the main source of uncertainty, then choose an action proportional to the evidence.
A worked calculation example
Assume a declared monitoring sample contains 20 eligible answers. Eight cite at least one page from the site, five mention the brand, three recommend it, and two identifiable referral sessions arrive during the same window. These are illustrative numbers, not SearchEngineAnswer performance data or an industry benchmark.
- Observed citation rate: 8 ÷ 20 = 40%.
- Observed brand-mention rate: 5 ÷ 20 = 25%.
- Observed recommendation rate: 3 ÷ 20 = 15%.
- Observed referrals per cited answer: 2 ÷ 8 = 25%.
The last calculation does not prove that two of the eight observed answers generated those sessions. The publisher does not see the complete population of answers shown to users, and the analytics window may include answers outside the monitored set. The responsible conclusion is that the four layers were observed in the same declared period, not that one caused the next.
Run a weekly review without mixing signals
- Export Google generative AI impressions by canonical page and date when the report is available.
- Export Bing cited pages and grounding queries with the same selected period.
- Segment analytics for identifiable AI referrers while retaining raw source and medium.
- Review outcomes for those landing sessions using a declared event definition.
- Annotate releases, outages, indexing changes, platform anomalies, seasonality, and material news.
- Report observation, interpretation, limit, action, owner, and next check as separate fields.
A useful weekly brief might say: “Five canonical pages gained reported Bing citations during the selected period; two also received identifiable ChatGPT referral sessions. The datasets do not expose a shared prompt population, so this is not evidence that the citations caused the visits. We will inspect the five pages’ source fit and recheck after the next complete reporting window.”
Avoid these measurement failures
- Adding Google generative AI impressions to Web impressions. Google says the subset is already included in Web totals.
- Calling Bing Citation Share market share. It is relative citation presence for a specific grounding query in Bing’s reported system.
- Treating a crawler request as an answer appearance. Logs establish access, not citation.
- Comparing unlike samples. A vendor’s fixed prompt set and a platform-native aggregate do not share a denominator.
- Dropping zeros. Excluding no-citation answers inflates observed rates and hides failure states.
- Backfilling causation. A content release and a later change in visibility can coincide without the release causing it.
- Reporting a score without the ledger. If a reviewer cannot inspect the rows, definitions, and evidence files, the score is not an auditable result.
Metric crosswalk
Use a common question, not a common label
Google, Bing and ChatGPT reporting surfaces expose different events. A crosswalk should align the business question while preserving the native definition.
- Discovery
- Was a page or brand eligible and surfaced?
- Visibility
- What was shown, and against which denominator?
- Visit
- Did a user click or arrive with a detectable referrer?
- Outcome
- Did the visit create value on the publisher’s property?
My takeaway: I map metrics to these four questions, then retain the platform field name beside every number. Renaming unlike fields “AI visibility” creates false comparability.
Primary documentation
- Google Search Console: Generative AI performance report
- Google Search Console: Impressions, position, and clicks
- Bing Webmaster Tools: AI Performance
- OpenAI: Publishers and developers FAQ
The downloadable ledger is a reporting template, not a platform standard. Update the field definitions when operator documentation or the monitored surfaces change.
Keep learning
Continue this topic
Next in this topic
How to Read a Search Patent Without Calling It a Ranking Factor
Earlier in this topic
How to run small SEO experiments without overclaiming
Research
Ask a question or join the discussion