How to Audit Sources in AI Local Recommendations
Separate business mentions, visible citations, click destinations, and profile cards; then classify source ownership and claim support without turning a sampled source mix into a ranking factor.
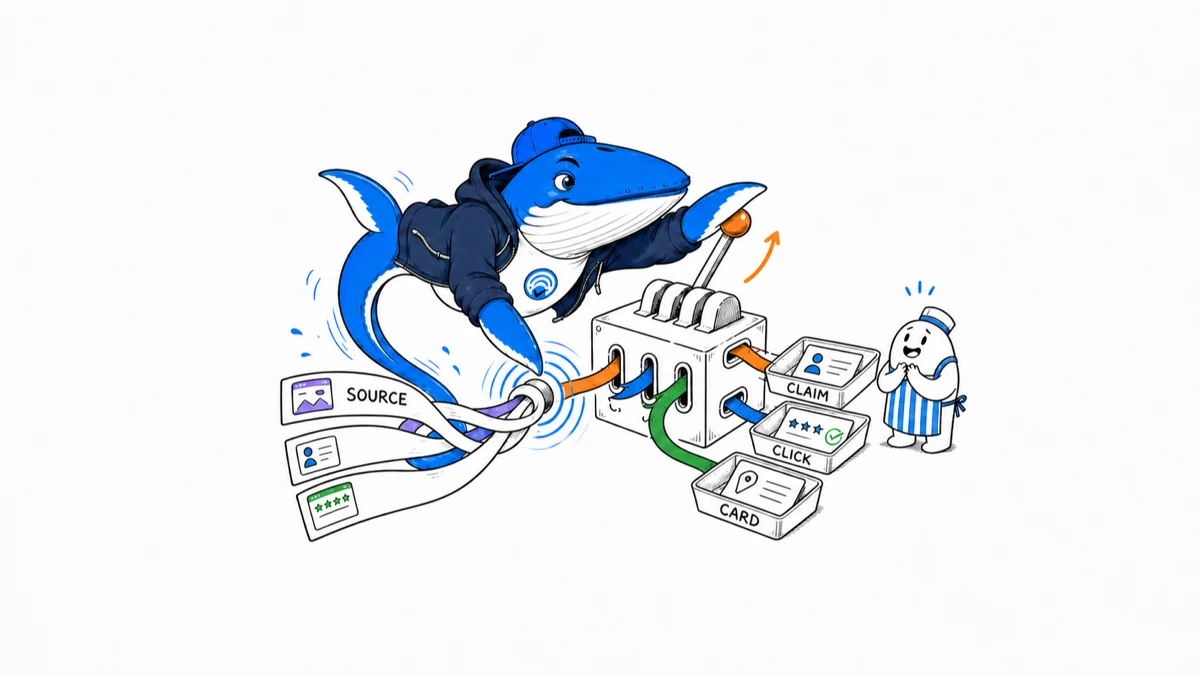
To audit the sources behind an AI local recommendation, record the business named, every visible source, the destination link, any profile or map card, and the claim each source actually supports. Classify those events separately. A directory link does not prove the directory caused the recommendation, and a business website used as a destination is not automatically the source of the answer’s claims.
What this guide does and does not do: it replaces an unfinished cross-platform experiment with a reusable source-audit method. It reports no source-frequency result, preferred-source ranking, or claim that one source type causes local recommendations.
The short answer
Save the complete response before annotating it. Freeze the product surface, account state, location, language, personalization, prompt, and run time. Then create one ledger row for each visible source and assign two codes: who owns the source and what role it plays in the answer.
The most useful conclusion is narrow: “Within these recorded responses, directory pages supplied 12 of 30 visible claim-support links, while first-party websites supplied most click destinations.” That describes the sample. It does not reveal an internal ranking system or prove that either source type caused a business to appear.
Use one source-role observation per row
An answer can recommend three businesses and cite five pages. One page might support opening hours, another a rating, and a third might simply be the “Visit website” destination. Treating the whole answer as one source event loses those distinctions.
The audit unit should be one visible source attached to one business, claim, or interface role in one saved run. Repeat the run ID when an answer has several sources. Preserve an explicit no_visible_source row when a business is named without a source.
Separate the recommendation from its evidence surfaces
A local answer exposes several observable events. Code each one rather than collapsing them into a single “visibility” label.
| Observed event | Question it answers | What it cannot establish |
|---|---|---|
| Business named | Did the response identify this entity? | Why the entity was selected |
| Recommendation wording | Was the business explicitly proposed for the task? | That a citation endorses the business |
| Visible source or citation | Which page did the interface attribute? | The complete retrieval set or a stable rank |
| Destination link | Where can the user click next? | Which source supported the recommendation reason |
| Profile, map, or place card | Which platform entity was rendered? | That the platform profile was the only information source |
Freeze the local-search environment
Local recommendations change when the location or product context changes. OpenAI’s current ChatGPT Search documentation says web-search responses can include citations and local results, may estimate a general location from an IP address, and can use precise device location when the user enables it. Google likewise documents that current location, language, device, recent searches, and personalization settings can affect Search services.
Record what you can observe. Do not invent a city from the recommendation. If the product reports only “approximate location,” use that label rather than treating it as a precise coordinate.
| Environment field | Minimum record | Why it matters |
|---|---|---|
| Product surface | ChatGPT Search, Google Maps, AI Mode, Perplexity Search, or another named surface | Interfaces and source contracts differ. |
| Account state | Signed in/out, plan, workspace if relevant | Availability and personalization can differ. |
| Location | Country, declared test city, and precise-location state | Nearby candidates and distances change. |
| Language and device | Interface language and desktop/mobile | Results and rendered cards may differ. |
| Context controls | Memory, personalization, prior conversation, and connected apps | The visible prompt may not be the only context. |
| Time | UTC timestamp and local date | Hours, availability, sources, and answers change. |
Capture the raw answer before classifying it
Save the exact prompt, full answer, visible Sources panel, cards, follow-up context, and screenshot before opening links or adding judgment. Opening a result can alter interface state, append tracking parameters, or make it difficult to reconstruct the original answer.
Assign a run ID and hash or file reference to the raw capture. The public ledger should not contain account identifiers, precise personal location, private prompts, or other sensitive material. Use a neutral test location and store private evidence separately.
Resolve the destination without erasing the observed URL
Keep both the URL shown by the product and the final destination after redirects. Remove fragments and clearly documented tracking parameters only in a separate normalized field. Do not overwrite the raw link, because a redirecting directory, reservation partner, profile page, or publisher can change the source-owner classification.
Record the final hostname, page title, HTTP outcome, and access date. Mark blocked, unavailable, login-gated, or ambiguous destinations rather than forcing them into a known category.
Classify who owns the source
Use a stable source-owner taxonomy across products. The categories describe the page you observed, not the reputation of its owner.
| Source type | Use when | Common ambiguity |
|---|---|---|
| First-party website | The business controls the destination domain and page. | A franchise location may sit on a corporate domain. |
| Platform profile or place entity | The page/card is owned by the search, map, or assistant platform. | The card can display facts gathered elsewhere. |
| Directory or marketplace | The site organizes providers, listings, bookings, or inventory. | A marketplace may also publish editorial guides. |
| Review platform | The page’s primary job is aggregating user ratings or reviews. | A directory can contain reviews without being review-led. |
| Publisher or editorial page | An identifiable publisher selected, compared, or reported on businesses. | Sponsored listings require a disclosure note. |
| Government or official registry | A public authority owns the record or guidance. | A contractor may host the service. |
| Social or user-contributed source | The visible page is primarily community or user content. | A business-owned social account remains platform-hosted. |
| Other, mixed, or unresolved | Ownership is compound or evidence is insufficient. | Do not choose the nearest-looking category. |
Classify what the source does in the answer
Owner and role are separate fields. A first-party website can support hours, act only as the click destination, or appear as an uncited related link. A directory can supply a price claim, a review summary, a booking button, or a comparison list.
Use one of these roles: claim_support, click_destination, profile_or_card, comparison_context, reservation_or_transaction, related_link, or no_visible_role. Add another row when one page performs two materially different roles.
Check the claim, not the domain’s reputation
Open the page and test whether it supports the adjacent statement: business identity, address, hours, price, availability, rating, review theme, accessibility, or another reason for the recommendation. Record supports, partly_supports, contradicts, not_found, or not_checked.
Perplexity’s current source-label documentation makes an important distinction: its Government, Academic, and Trusted labels apply to a domain, not an individual page or claim. A label is not an accuracy guarantee or endorsement, and no label is not a negative judgment. Keep any platform label in its own field; do not substitute it for passage review.
Expect a profile card to combine several inputs
Google’s documentation on how Business Profile and local-result information is sourced lists publicly available web content such as an official business website, licensed third-party data, user contributions, owner-supplied information, and information based on Google’s interactions with a place. A rendered profile therefore does not identify one exclusive upstream source.
Code the profile or place card as the visible surface. Then record any separately visible website, review, directory, or publisher links. If the audit cannot trace a displayed field to an upstream page, mark the origin unresolved.
Keep no-source, multi-source, and compound cases
Do not discard an answer because it lacks citations. A business named with no visible source is an observable outcome and belongs in the denominator. Likewise, preserve answers that cite several owners, show a card plus a website, or send the click through a booking partner.
Use an exclusion only when the run itself is not comparable: wrong location, changed prompt, unavailable product, unresolved account state, incomplete capture, or a blocked destination under a rule declared before review.
Use the local classifier and CSV ledger
Open the AI local recommendation source classifier. It accepts one source-role observation at a time, keeps the rows in the current browser tab, summarizes included source types and roles, and exports a CSV. It does not fetch URLs, resolve redirects, classify domains automatically, or send analytics.
For a sheet-first workflow, download the source-audit ledger. Delete all rows marked EXAMPLE-REMOVE. The example values demonstrate row shape only; they are not observed platform results.
Calculate a source mix with the right denominator
Count source observations separately from answer runs and recommended businesses. If 10 runs produce 24 visible source rows, a first-party share of 8/24 describes visible sources, not the share of runs, businesses, or recommendations. Report both counts when the distinction matters.
| Measure | Denominator | Safe interpretation |
|---|---|---|
| Visible source-type share | Included visible source rows | Composition of attributed sources in the sample |
| Runs with no visible source | Comparable answer runs | How often the interface exposed no source for the coded business |
| Claim-support rate | Checked claim-source rows | How often the opened page supported the coded claim |
| Destination-type share | Included click-destination rows | Where the interface sent users next |
| Attribute-conflict rate | Rows with a comparable attribute check | How often visible sources disagreed within the audit |
Do not report a preferred source or ranking factor
A source type can appear frequently because it covers many businesses, exposes structured facts, publishes useful comparison pages, is accessible to the product, or matches the sampled tasks. The output does not reveal the candidate set, weighting, rejected sources, or causal path to recommendation.
Google describes relevance, distance, and prominence as the main factors behind its own local results. Its local-ranking guidance does not convert a source-audit frequency into a ranking factor. Other AI products have different systems and interfaces. Keep results broken out by product surface, location, task, and date.
A 12-step source-audit workflow
- Define the local decision and exact prompt family.
- Choose neutral test locations and record privacy boundaries.
- Freeze product surface, account, language, device, location, and personalization.
- Assign a run ID and capture the complete answer before annotation.
- Record every named business and whether the wording is a recommendation.
- Create one row for each visible source, destination, card, or no-source outcome.
- Preserve the observed URL and resolve the final destination separately.
- Classify source owner and answer role independently.
- Check the cited page against the adjacent claim.
- Record conflicts, missing fields, and predeclared exclusions.
- Calculate source, role, and support distributions with explicit denominators.
- Report the observed sample without causal, universal, or ranking language.
A 100-metro study shows why retrieval state belongs in the audit
A new study of AI provider recommendations in local service markets compared recommendations with Medicare clinician and facility registries and the SEC investment-adviser registry across the 100 largest U.S. metropolitan areas.
Without web search, the paper reports that 4% of open-weight doctor recommendations and 11% of proprietary-model recommendations matched a clinician in the queried city. The authors say the open-weight matches were name coincidences. With search enabled, 64% to 71% matched real providers in the corresponding domains.
The study also reports that advisory firms recommended without search had SEC misconduct disclosures at 3.6 times the registry base rate after adjusting for firm size. With search, the recommended firms were significantly below that baseline. Restaurant recommendations showed a three-to-five-times review-count premium, while the reported rating premium was no more than 0.1 stars.
| Field | Record | Decision it supports |
|---|---|---|
| Retrieval state | Search on, search off or unknown | Separates recalled names from retrieved providers. |
| Registry match | Entity, city, domain and identifier | Tests whether the recommended provider exists in the requested market. |
| Disclosure baseline | Recommended-set rate and registry base rate | Avoids interpreting a raw count without the market denominator. |
| Popularity measure | Review count and rating separately | Distinguishes visibility volume from quality score. |
| Verification disclosure | Whether the answer signals uncertainty or live lookup | Shows whether the reader can tell a recalled name from a checked recommendation. |
The paper does not prove that search always improves every local recommendation or that review count causes selection. It does provide a strong reason to record retrieval state, registry validity and market baselines alongside visible citations.
The publication quality gate
The audit is ready when another reviewer can reconstruct the prompt, environment, answer, business identity, visible URL, resolved owner, source type, role, claim-support decision, exclusion, and denominator. It is not ready when sources are counted from screenshots alone, redirects are ignored, business websites and profile cards are merged, or destination links are presented as grounding evidence.
Use a second reviewer for ambiguous ownership and claim support. Preserve disagreement rather than forcing a clean distribution.
Connect source evidence to visibility and attribution
Use the ChatGPT prompt-family measurement guide when building repeated runs. The AI visibility measurement crosswalk separates appearance from referral and business outcome, while the Business Profile completeness audit helps review the first-party and profile facts that local surfaces may display.
Method, sources, and update note
This guide was rebuilt on September 1, 2026, from an unfinished cross-platform research protocol. It adds a source-role ledger, a browser-local classifier, link-resolution rules, a claim-support decision, explicit denominators, and safe reporting language. Product behavior claims are limited to the linked official OpenAI, Google, and Perplexity documentation. The article contains no source-frequency result.
Update trigger: recheck the method when a product changes local-result cards, citation or Sources panels, location controls, personalization, source labels, redirect behavior, or publisher reporting.
Keep learning
Continue this topic
Next in this topic
Google Generative-AI Search Control: Record Scope, Baseline and Rollback
Earlier in this topic
How to Audit ChatGPT Job Listings Before You Apply
AEO & AI Search
Ask a question or join the discussion