ChatGPT Search Prompt Families: Run a 31-Field Visibility Study
Measure controlled ChatGPT Search runs with prompt families, frozen environments, repeated samples, citation review and separate referral evidence.
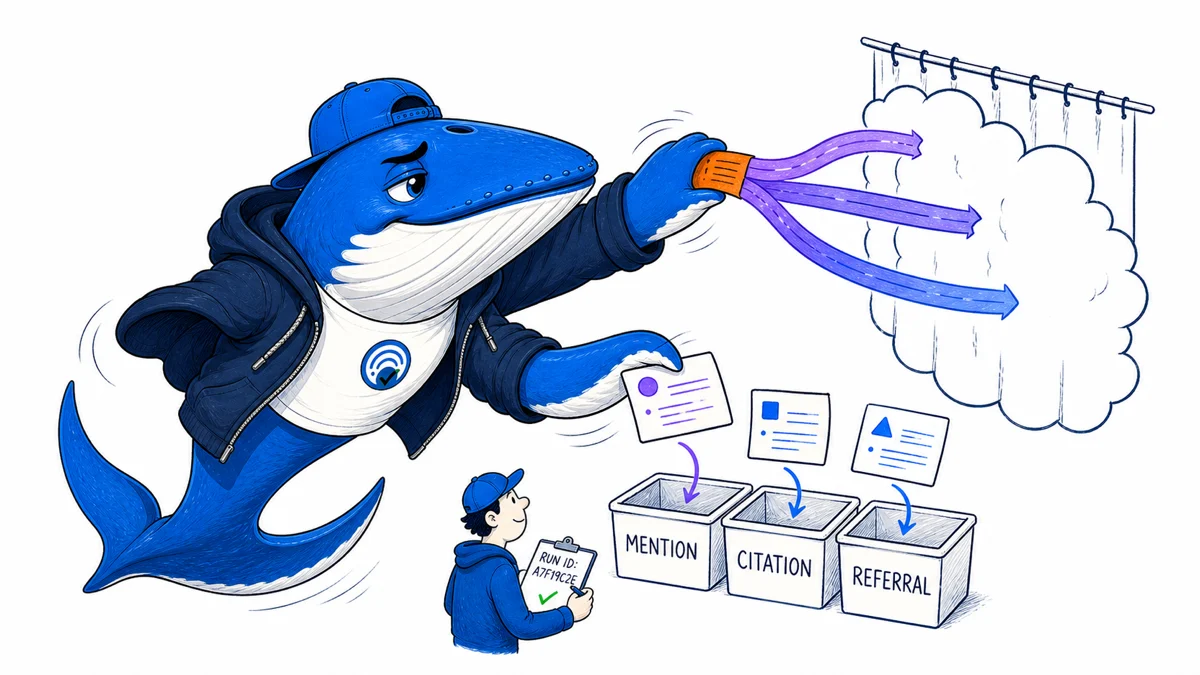
Direct answer: an exact-prompt tracker can record what appeared in a controlled ChatGPT Search run, but it cannot treat the prompt string as the full retrieval query. OpenAI documents that ChatGPT Search may rewrite one question into one or more targeted searches. It may also use general location, optional device location and, when enabled, relevant memory. A defensible brand-visibility study therefore needs prompt families, frozen environment fields, repeated runs and separate coding for mentions, citations and referrals.
This guide supplies that measurement contract. It does not claim to reconstruct OpenAI’s candidate set, weighting or rejected sources. The downloadable 31-field prompt-family run ledger contains example rows marked EXAMPLE-REMOVE; replace them before using the file for a real study.
Why one saved prompt is not the complete search input
OpenAI’s current ChatGPT Search documentation, retrieved August 29, 2026, says the product may translate a question into multiple targeted queries and may issue more specific searches after reviewing initial results. The same page explains that approximate location can come from an IP address, precise device location is optional, and relevant memory may influence a rewritten query when memory is enabled.
Those are documented inputs to retrieval, not a public ranking formula. A tracker can preserve the visible question, environment and answer. It usually cannot observe every rewritten query, the complete candidate pool, the scoring process or the reasons a URL was rejected. Report the layer you observed instead of assigning a stable “ChatGPT rank” to hidden machinery.
| Layer | Recordable evidence | Boundary |
|---|---|---|
| Input | Prompt, prompt-family ID, conversation state and run time | Prior context or memory may be incomplete unless deliberately controlled |
| Environment | Interface, plan, signed-in state, language, location controls and memory state | Product experiments and server-side changes may remain unknown |
| Answer | Visible text, sources, links, order, caveats and errors | A cited URL does not expose the full candidate set or guarantee recurrence |
| Referral | Publisher analytics for tagged visits such as utm_source=chatgpt.com |
A citation can occur without a click; analytics does not count every appearance |
Define the reader task before writing prompts
Start with the decision a real user is trying to make. “Best accounting software” and “how to reconcile an invoice overpayment” are not interchangeable prompts about the same brand. One is a comparison task; the other is troubleshooting. Group prompts by task before comparing source visibility.
Give each family a stable ID and one explicit scope. Useful families include discovery, comparison, verification, troubleshooting, local and transactional tasks. Do not build a family by changing only punctuation or swapping one synonym. The variants should represent natural ways capable readers express the same underlying need.
Build paraphrase families instead of keyword replicas
A small family can include a direct question, a constraint-led version, a scenario and a follow-up. For example, a comparison family might ask for options, then narrow by team size, data residency or budget. Save each wording as its own prompt ID while keeping the family-level reader job constant.
| Variant | What changes | What stays fixed | Use in analysis |
|---|---|---|---|
| Direct | Plain statement of the task | Reader job and eligibility constraints | Baseline wording |
| Constraint-led | Plan, geography, format or risk appears first | Decision being made | Tests whether a material constraint changes sources |
| Scenario | Task is expressed through a realistic situation | Required outcome | Tests vocabulary and contextual variation |
| Follow-up | Runs after a declared opening question | Saved conversation sequence | Measures context-dependent behavior separately |
Keep prompt families small enough to review manually. More prompts create more rows, not automatically better coverage. Add a variant because it represents a real expression of the task, not because a dashboard rewards volume.
Freeze the environment that can change the result
Record the product surface, device class, signed-in state, plan, language, approximate country or city boundary, device-location setting, memory state and conversation mode. OpenAI’s current Memory FAQ explains that memory can be disabled and that Temporary Chats do not use or create memories. Do not store a precise address, personal memory content or account identifier in a public artifact. “Location allowed: city level” is normally enough for a method record.
Run local and non-local prompt families separately. OpenAI documents that location can shape relevant searches and local answers, so mixing cities in one denominator makes the result hard to interpret. If memory cannot be reliably disabled or audited in the chosen environment, label that run uncontrolled rather than pretending it matches a clean baseline.
Repeat runs without manufacturing a ranking score
Choose the number of runs before reviewing answers. Preserve errors and missing answers in the denominator. A useful statement is: “The brand appeared in 7 of 10 completed runs for this prompt family and frozen setup.” “The brand ranks at 70% in ChatGPT” invents a stable ranking unit that OpenAI does not document.
Record a run ID, exact timestamp and raw-output reference. A regenerated answer is a new run. A changed prompt, location, memory state or conversation sequence is a new condition. Do not replace a failed row with a successful rerun while keeping the original denominator.
Code mentions, citations and referrals as separate outcomes
A brand name in the prose, a clickable citation to the brand’s domain, a citation to a third-party page about the brand and a referral visit are four different observations. Store them in separate columns. This follows the same evidence boundary used in the AI visibility measurement crosswalk and the OpenAI publisher-controls guide.
| Observed outcome | Record | Safe interpretation | Do not infer |
|---|---|---|---|
| Brand mention | Name, variant and answer span | The answer mentioned the brand in this run | That the brand’s site was retrieved |
| Owned-domain citation | Resolved URL, source label and answer position | The response linked the owned domain in this run | A stable rank, endorsement or future recurrence |
| Third-party citation | Resolved URL, publisher and relationship | A third party supplied visible evidence about the brand | That the owned page was eligible or considered |
| Referral | Landing page, source/medium, time window and consent-safe outcome | A tagged visit reached the site | All mentions or citations generated visits |
Audit whether a citation supports the adjacent claim
Open each cited URL and record its resolved destination. Check whether it directly supports the nearby statement, supports only part of it, conflicts with it or is inaccessible. Search citations can be incomplete or outdated; OpenAI explicitly tells users to open sources and verify important claims.
Keep the answer capture and claim-support review separate. A tracker that counts URLs but never opens them measures visible sourcing, not evidence quality. For a deeper review, use the evidence-led publishing guide to classify facts, observations and inferences.
Use the 31-field run ledger
The CSV’s unit of analysis is one prompt run. It joins the family, prompt, environment, visible answer, source coding, publisher-referral check, reviewer decision and method limitation. The two illustrative rows are labeled EXAMPLE-REMOVE and are not observations from SearchEngineAnswer.
Keep raw outputs in a restricted evidence store when they contain conversation context or personal data. The public ledger should contain a safe reference, a short evidence note and aggregate results. It should not expose account IDs, precise locations, memory contents, private prompts, personal identifiers or authentication data.
Compare tools only after comparing their contracts
Two vendors may use the same label for different methods. Before comparing scores, check prompt-family design, geography, signed-in state, memory handling, run frequency, repetitions, source parsing, error treatment and denominator. The SEO and GEO tool-score evaluation guide provides a broader buyer-side review.
If a vendor cannot document those fields, treat its score as a product-specific indicator. It may still be useful for directional monitoring, but it is not comparable to a separately sampled study merely because both results are percentages.
Turn changes into investigations, not guarantees
A prompt-family tracker is most useful as an alert. Investigate when an owned source disappears across repeated runs, a third party repeatedly supplies stale evidence, an important product fact is absent, or citations move to a page that answers the task more completely. Check crawl eligibility, factual clarity, page freshness and competing evidence before editing copy.
Do not paste tracked prompts into headings or promise inclusion after a rewrite. The justified outcome is a reproducible observation with a declared setup. The next measurement should use the same contract, preserve product drift and explain any change to the sample before comparing periods.
Method note: This page is a measurement protocol, not a completed ChatGPT visibility study. It was rebuilt from current OpenAI documentation retrieved August 29, 2026. SearchEngineAnswer did not receive hidden query logs or ranking data from OpenAI.
Keep learning
Continue this topic
Next in this topic
Web Bot Auth for Publishers: Verify Signed AI Agents
Earlier in this topic
OpenAI Publisher Controls: Crawl Access, Citations and Referrals Are Different Outcomes
AEO & AI Search
Ask a question or join the discussion