You.com Answer API: Audit Citations, Excerpts, and Uncited Claims
Audit You.com Answer API citations, excerpts, live-source support and uncited claims with a 28-field downloadable claim-source ledger.
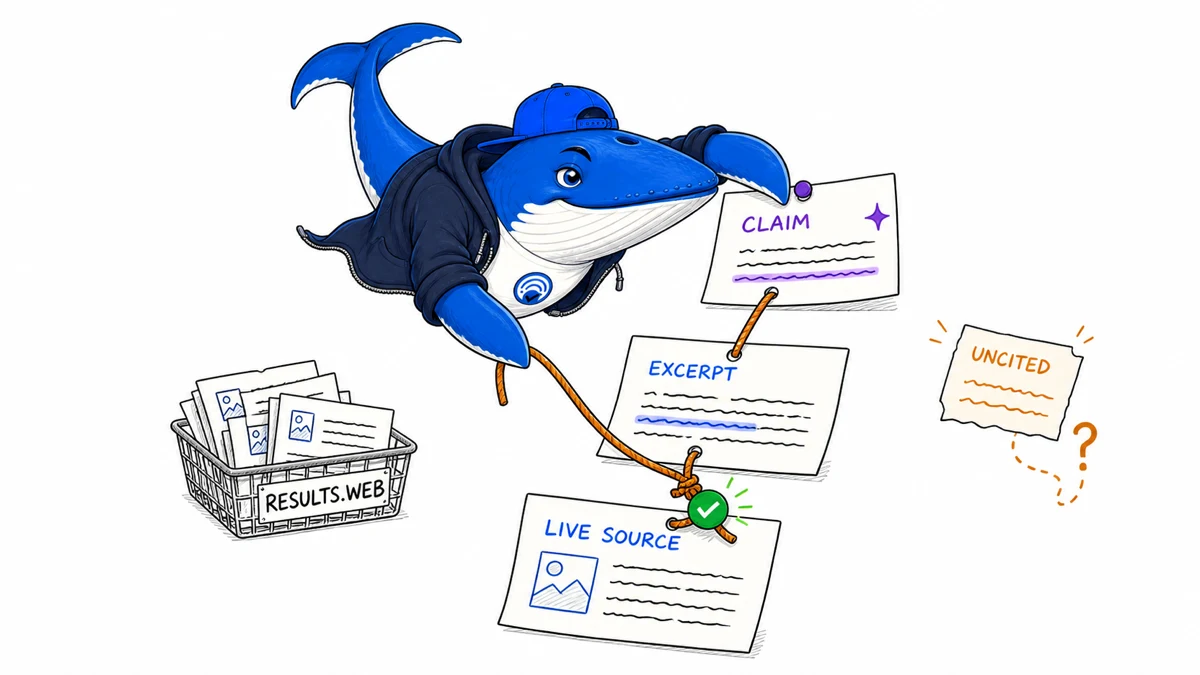
Direct answer: A You.com Answer API response gives you three evidence layers to audit: the Markdown answer, the ordered citations array with source URLs and excerpts, and results.web containing web results considered during synthesis. Verify the mapping between all three before treating “citation-backed” as proof that every material claim is complete and decision-ready.
This rebuilt guide includes a 28-field citation audit ledger. It records the request controls, response fields, claim, nearby citation, excerpt match, live-page support, source quality, reviewer decision, and rerun date. All included rows are marked EXAMPLE-REMOVE; they are method examples, not measured API results.
Record the current response contract
The current You.com Answer API guide describes a managed pipeline that takes one query, retrieves web results, extracts supporting content, and synthesizes a cited answer in one request. You do not choose the underlying search strategy, page reads, prompts, or model. Optional controls cover freshness, country, language, safe search, and included, excluded, or boosted domains.
Every response includes an answer field with Markdown and numbered inline citations, a citations array in citation order, and results.web for web results considered during synthesis whether they were cited or not. A citation item includes a source URL and one or more excerpts.
You.com says its pipeline verifies that each citation exists in the supplied source text and supports the answer before returning it. Treat this as the documented product contract. Your audit tests whether the returned evidence supports your own publication or application decision; it is not a claim that You.com performs no verification.
Freeze the request and response before rendering
Save the endpoint, request timestamp, application version, query, freshness, country, language, safe-search value, and domain controls. Preserve the raw response before removing whitespace, renumbering references, transforming Markdown, or merging source lists. A presentation layer can break the link between a claim and its citation even when the API response was internally consistent.
Keep the API key and authorization header out of the audit. Use a non-secret run alias and store sensitive operational logs separately. If the question contains confidential or personal information, do not copy it into a public artifact.
| Layer | Record | Do not infer |
|---|---|---|
| Request | Query and controls | The exact hidden retrieval strategy |
| Answer | Markdown and inline citation numbers | Completeness or correctness by formatting alone |
| Citations | Ordered sources and returned excerpts | Independent authority or stable selection |
| Web results | Results considered during synthesis | Every page available on the web |
Split the answer into reviewable claims
Do not score a paragraph as one unit. Split it into factual claims, calculations, interpretations, recommendations, and uncertainty statements. Give each material claim a stable ID. Record the citation number immediately adjacent to the claim and whether the claim has no citation.
A sentence can contain several propositions with different evidence. One excerpt may support the product release date but not a performance comparison attached to it. Split the propositions instead of awarding full support because one part is cited.
Review absence as well as presence. A well-cited answer can omit a material exception, jurisdiction, date, denominator, or conflicting source. Completeness is a reader-job judgment that the citation mapping alone cannot settle.
Test the returned excerpt and the live source separately
First compare the returned claim with the citation excerpt. Classify the relationship as direct, partial, qualified, conflicting, absent, or inaccessible. Then open the source URL and inspect the live page. Confirm the excerpt appears in the page or in an accessible authoritative version, and read enough surrounding context to detect a changed subject, missing qualifier, outdated date, or quoted opinion.
| Class | Meaning | Editorial action |
|---|---|---|
| Direct | The excerpt and context support the complete claim | Continue source-quality and freshness review |
| Partial | Only part of the claim is supported | Split, narrow, or add evidence |
| Qualified | Support depends on a condition omitted from the answer | Add the condition beside the claim |
| Conflicting | The source context pushes against the answer | Reject or rewrite the claim |
| Absent or inaccessible | No usable support can be verified | Do not publish the claim as verified |
A verbatim excerpt match proves a textual relationship to the content supplied to the model. It does not, by itself, prove the source is correct, current, independent, applicable to the question, or the best available authority.
Review ownership, freshness, and source concentration
Classify the factual owner: official documentation, standard, law or regulator, original research, dataset, qualified analysis, reporting, community report, vendor marketing, or unknown. A vendor page is usually the closest source for its current API field but not independent proof of its benchmark quality.
Record publication or update time, retrieval time, geography, product version, and access state when they constrain the claim. Follow redirects and preserve the resolved URL. If several citations repeat one announcement through syndication, count the underlying factual owner rather than treating the links as independent confirmation.
The current response schema no longer includes an authors field in Answer API source results. You.com’s July 15, 2026 changelog records its removal. Do not build current source-quality logic around that deleted field; resolve publisher and author information from the source page when the decision needs it.
Compare cited sources with considered results
The results.web list creates a useful audit boundary. Record whether the source attached to a claim was cited, merely considered, or absent from the returned result set. This can expose cases where a stronger primary source was retrieved but the answer cited a secondary page, or where several considered results repeat the same factual owner.
Do not interpret order in results.web as a public search ranking or durable recommendation unless the documentation defines it that way. It is an application response from a managed pipeline. A later run can differ as the web, index, filters, and synthesis system change.
| Question | Record | Why it matters |
|---|---|---|
| Was it cited? | Citation index and claim ID | Preserves the explicit answer mapping |
| Was it considered? | Position or presence in results.web | Shows part of the returned retrieval set |
| Who owns the fact? | Primary owner and source type | Prevents syndicated copies from looking independent |
| Was a closer source available? | Reviewer note and replacement URL | Turns the audit into a repair decision |
Use the 28-field citation audit ledger
Download the You.com Answer API citation audit ledger. Each row represents one claim-source relationship from one preserved run. Remove or replace all EXAMPLE-REMOVE rows. The examples show the allowed values and are not evidence about You.com’s output quality.
The ledger separates returned evidence from reviewer evidence. It stores the citation excerpt and excerpt-match status, then records whether the live page supports the claim, source authority, freshness, conflicts, the editorial decision, and the next review date.
| Decision | Use when | Next step |
|---|---|---|
| Accept | Support, authority, scope, and freshness fit | Keep the source beside the claim |
| Qualify | The claim needs a visible condition or limit | Rewrite and preserve the qualifier |
| Replace source | A closer factual owner is available | Cite and verify the primary source |
| Remove | Support is absent, conflicting, or unnecessary | Delete the claim or collect new evidence |
Design a repeatable evaluation without inventing a benchmark
Freeze a small query set before reviewing outputs. Include stable factual questions, time-sensitive questions, questions with jurisdiction or product-version boundaries, and questions whose correct answer should express uncertainty. Preserve errors, empty results, and uncited claims. Define the support rubric and reviewer rules in advance.
Keep citation support, factual correctness, completeness, source authority, latency, and cost as separate measures. Report the sample, date, controls, and denominator for each result. One run can demonstrate the audit method; it cannot establish population-wide accuracy or stable source selection.
Use the AI visibility measurement crosswalk when comparing citation and referral metrics, and the small-experiment workflow for baselines, confounders, and stopping rules. Do not merge an API citation audit with aggregate brand visibility.
Citation grading
Grade answer support claim by claim, not response by response
One well-supported paragraph does not make the entire API response reliable.
- Direct
- The cited text supports the same claim and qualification.
- Partial
- The source supports the topic but not the full statement.
- Contradictory
- The source conflicts with the answer.
- Uncited
- No visible source supports the claim.
My takeaway: My acceptance threshold would be defined before testing and weighted toward consequential claims. A polished response can still fail if its most important statement is only partially supported.
Sources and method
- You.com: Answer API overview
- You.com: current OpenAPI specifications
- You.com changelog: removed authors field
- You.com developer changelog
- SearchEngineAnswer editorial policy
Documentation was rechecked on August 29, 2026. This page describes a verification method and worksheet. It does not claim an API key was used, report an independent Answer API accuracy test, or reproduce You.com’s benchmark and latency claims.
Extraction, transport and attribution belong in one audit
Citation quality cannot be evaluated independently from the endpoint, response shape and extraction mode that produced it. These supporting tests are consolidated here so a reader can trace the full pipeline instead of comparing isolated API changes.
| Change | What it affects | Best next check |
|---|---|---|
| You.com Highlights vs Full-Page Extraction Test | You.com now lets Search API users request relevant highlights or full-page HTML and Markdown. Use this protocol to compare citation support, answer coverage, latency, and tokens without inventing a winner. | Compare claim support, coverage, tokens, latency, failures and answer quality on the same frozen query set. |
| You.com Web Search GET vs POST: Cacheability and Domain-Filter Semantics | Choose You.com Web Search GET or POST by comparing cache behavior, domain-list encoding, URL limits, filter precedence, redacted keys, and time-sensitive results. | GET uses comma-separated domain fields; POST can express domain arrays directly. |
| You.com Removed the authors Field: Keep Attribution Pipelines Stable | Make author metadata optional, preserve source identity, and test downstream attribution systems after You.com removed the authors field from v1 and Answer API results. | Check storage, exports, templates, analytics, search indexes, and entity tables. |
Originally reported 2026-08-16
You.com Highlights vs Full-Page Extraction Test
Why it matters: You.com now lets Search API users request relevant highlights or full-page HTML and Markdown. Use this protocol to compare citation support, answer coverage, latency, and tokens without inventing a winner.
Next check: Compare claim support, coverage, tokens, latency, failures and answer quality on the same frozen query set.
Direct answer: You.com added an extraction object to POST /v1/search on August 11, 2026. A client can request relevant highlights for token-sensitive workflows or retrieve a full_page representation as Markdown or HTML. The modes expose different amounts and shapes of evidence.
There is no honest universal winner without a task and test. Highlights can reduce context volume but may omit a passage needed for a complex claim. Full-page extraction can preserve more context while increasing tokens, latency and irrelevant material. This protocol compares both without presenting an unrun benchmark as a result.
Map the response contract before comparing quality
| Mode | Returned content | Primary risk |
|---|---|---|
| Highlights | contents.highlights with relevant passages; ordinary snippets omitted | Needed context falls outside selected passages |
| Full page: Markdown | contents.markdown plus default snippets | Navigation and repeated page material consume context |
| Full page: HTML | contents.html plus default snippets | Markup noise and larger payloads complicate parsing |
Save the raw Search API response before cleaning it. The source URL, title, retrieval time, extraction mode, returned order and errors are part of the evidence object.
Freeze a query-and-answer fixture
Use at least four task classes: a narrow fact, a multi-condition explanation, a comparison that needs evidence from more than one source, and a current product fact. Add one zero-result or inaccessible-page case. Freeze exact queries, domain filters, country and language settings, freshness controls, result count, model, answer instructions and acceptance rubric.
Run both extraction modes against the same query in close succession. If the result set changes, compare only overlapping URLs or record the retrieval difference as a separate variable. Otherwise the test confuses extraction with search ranking and index freshness.
The existing GET versus POST guide covers endpoint and cache semantics. The citation-ready passage guide explains claim-to-source review.
Score evidence and efficiency separately
| Metric | Definition | Evidence to save |
|---|---|---|
| Claim support | Material answer claims directly supported by a retrieved passage | Claim, passage, URL and reviewer label |
| Coverage | Required task elements answered with evidence | Frozen rubric and missing elements |
| Source fidelity | Answer preserves conditions, uncertainty and attribution | Source snapshot and answer text |
| Input tokens | Tokens sent into the answer step | Tokenizer/version and per-source counts |
| Latency | Elapsed search, extraction and answer time | Start/end timestamps and retry state |
| Failure rate | Empty, inaccessible, truncated or malformed sources | Raw error and HTTP/extraction state |
Report medians and tail values for tokens and latency. For citation support, preserve reviewer disagreements instead of forcing a clean score.
Calculate citation value per 1,000 tokens carefully
A practical efficiency measure is supported material claims ÷ input tokens × 1,000. Publish the numerator and denominator, not only the ratio. A compact mode can score well while missing an essential claim; a full-page mode can support more claims but waste context.
Use a release gate: no extraction mode wins when it increases unsupported material claims, hides contradictory source language, or fails the task’s mandatory element; even if its token ratio improves. Choose a default by task class and keep a fallback when extraction returns insufficient evidence.
Status: this is a reproducible protocol, not a completed benchmark. Search Engine Answer has not run a production You.com key against this fixture, so no measured advantage is claimed.
Primary documentation
Originally reported 2026-08-11
You.com Web Search GET vs POST: Cacheability and Domain-Filter Semantics
Why it matters: Choose You.com Web Search GET or POST by comparing cache behavior, domain-list encoding, URL limits, filter precedence, redacted keys, and time-sensitive results.
Next check: GET uses comma-separated domain fields; POST can express domain arrays directly.
Direct answer: You.com documents GET and POST forms for Web Search that use the same underlying search logic but encode complex inputs differently. GET can participate in HTTP caching when the cache key varies correctly; POST is safer for long or structured domain lists. Choose the method from request size, cache policy, observability, and filter semantics; not from an assumption that one ranks differently.
Matching request meaning does not guarantee identical or stable result ordering over time. Search indexes, freshness, live-crawl behavior, location, provider updates, and cache age can change the response. Infrastructure cacheability is not a search ranking signal.
Normalize one request before comparing methods
Create one canonical request object containing query, country or locale, freshness, safe search, result count, live-crawl option, include domains, exclude domains, boost domains, and every other result-changing field. Generate GET and POST requests from that object so method comparison cannot drift through two hand-maintained builders.
For GET, serialize supported domain fields exactly as documented; repeated parameters are not a substitute for the required comma-separated form. For POST, preserve array order only when the API says it matters and normalize duplicate domains before sending.
| Field | GET | POST |
|---|---|---|
| Encoding | Query string | JSON body |
| Domain lists | Comma-separated field | Structured arrays |
| Caching | Possible with complete key and Vary | Not normally shared-cacheable by default |
| Best fit | Short repeatable request | Long or complex filters |
Make cache keys and credentials safe
Never place the API key in the URL. If an intermediary caches GET responses, its key must cover the full normalized URL and authorization context, and its response handling must respect the documented Vary behavior. Logs, analytics, and error trackers should redact credentials and sensitive queries.
Set an explicit cache lifetime that matches the user job. A research query requiring current results should not receive a day-old shared response because it was cheaper. Save cache hit or miss, stored time, age, and purge reason in test records.
Test domain-filter semantics
Test include, exclude, and boost behavior individually before combining them. You.com says boosted domains receive a relative preference but are not mandatory; include and exclude semantics are stronger constraints. Preserve an empty result when filters are too narrow rather than silently removing the filter.
Build cases for long lists, duplicates, subdomains, paths, commas, invalid combinations, non-ASCII domains, URL-length rejection, and a list that yields no results. Compare normalized request meaning, response status, result destinations, and a response hash while preserving the date.
Choose the method and preserve time
Use GET when the request is short, observable, and safely cacheable under your infrastructure. Use POST when the body is complex, long, or should not enter URL-oriented logs. Keep one shared validator so switching methods does not change domain precedence or defaults.
A reproducible report names the method, normalized request, cache state, API version, date, and response. It can show equivalence or difference for that sample; it cannot claim one method has a permanent ranking advantage.
Use the AI visibility tools buyer’s matrix for authentication and privacy, and the small-experiment method for repeatable runs.
Choose highlights or full-page extraction explicitly
You.com’s August 11 changelog documents an extraction object for POST /v1/search. The highlights mode returns relevant passages in contents.highlights and accepts a token budget; the full_page mode returns page content in contents.markdown or contents.html. The changelog also says default snippets are omitted when either extraction mode is requested.
This changes the response contract, not merely the transport. A fair GET-versus-POST study must record the extraction mode, token budget, requested fields, returned fields, page count and error state. Do not attribute a difference to HTTP method when one arm silently receives snippets and the other receives extracted page content.
The safe conclusion is bounded to You.com’s documented API behavior as of August 11, 2026. It does not establish that one extraction mode produces better rankings, citations or downstream answers.
Primary documentation
Originally reported 2026-08-09
You.com Removed the authors Field: Keep Attribution Pipelines Stable
Why it matters: Make author metadata optional, preserve source identity, and test downstream attribution systems after You.com removed the authors field from v1 and Answer API results.
Next check: Check storage, exports, templates, analytics, search indexes, and entity tables.
Keep learning
Continue this topic
Next in this topic
X Search Is Switching From Per-Call to Per-Result Pricing
Earlier in this topic
How to use AI for content briefs without publishing generic work
Tools & Workflows
Ask a question or join the discussion