Microsoft Web IQ: Audit Evidence Objects Before Trusting Benchmarks
Audit Web IQ source passages, ownership, support, freshness, duplication, context selection, latency, and failures without inheriting vendor benchmark claims.
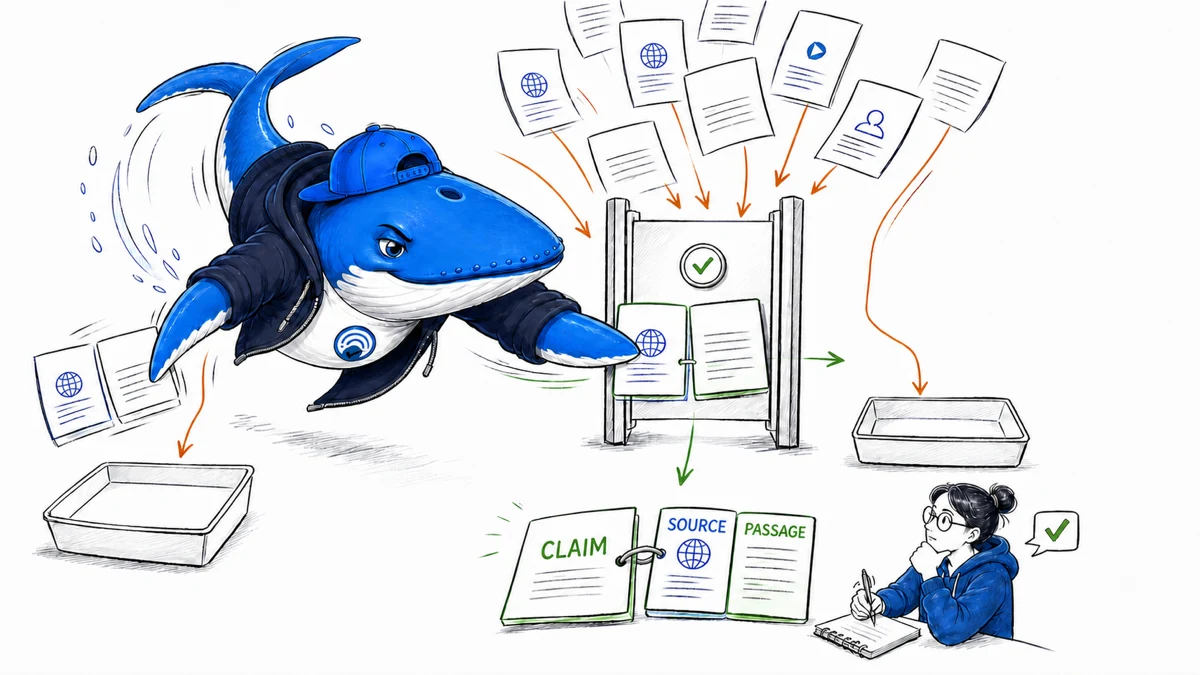
Direct answer: evaluate Microsoft Web IQ by preserving its evidence objects before a model turns them into an answer. Audit source ownership, canonical URL, passage support, freshness, duplication, context selection, latency, and failures as separate fields. Do not inherit Microsoft’s benchmark conclusions as if your application reproduced them.
Microsoft describes Web IQ as a grounding system for AI agents built on the Bing index. Its June 2026 material says the system returns passage-level structured evidence from web, news, image, and video sources. Microsoft also reports higher grounding satisfaction, sub-165 ms p95 latency, and about 2.5× speed versus its comparison cohort. Those are vendor-reported results under stated internal conditions, not a benchmark completed by Search Engine Answer.
Define the product and access state first
Microsoft’s announcement calls Web IQ a suite of AI-native grounding APIs, while its public page directs prospective users to express interest. Record the exact access path, contract, API surface, version, region, quota, and response schema available to your account. Do not build a test from a marketing diagram and assume undocumented fields exist.
Keep Web IQ separate from Bing consumer results, Bing Search APIs, Bing Webmaster Tools AI Performance, Copilot answers, Foundry IQ, and Work IQ. They may share infrastructure or naming, but their request contracts, metrics, and user outcomes are different.
| Surface | Observed object | Useful question | Do not infer |
|---|---|---|---|
| Web IQ | Grounding response and evidence objects | What evidence did the retrieval layer return? | Consumer Bing rank or aggregate publisher visibility |
| Application context | Selected, ordered, truncated evidence | What reached the model? | That every returned object was used |
| Generated answer | Claims and citations | Did the answer remain inside the evidence? | Retrieval quality from fluency alone |
| Vendor benchmark | Microsoft chart and method note | What does Microsoft report? | Your application’s quality or latency |
Preserve the evidence object before transformation
Save the raw response or an approved redacted copy before reranking, deduplication, summarization, or prompt assembly. Assign stable run, query, and object IDs. Record the content type, displayed URL, resolved URL, canonical URL, publisher, dates, passage, structural metadata, and any score or confidence field the current schema exposes.
Hash the passage or raw record so later reviews can distinguish the retrieved object from a changed source page. If terms or data policy prevent storing full text, preserve the permitted identifiers, short verification excerpt, hash, retrieval time, and access restriction. Do not reconstruct a missing evidence object from the final answer.
Audit passage entailment, not keyword overlap
Split the generated answer into material claims. For each claim, ask whether the retrieved passage directly supports it, supports only part, supplies context, conflicts, or provides no identifiable support. Preserve scope, date, unit, population, geography, and uncertainty. A passage containing the same nouns can still fail to entail the claim.
Open the canonical source. Confirm that the passage exists in context and that the publisher closest to the fact owns the claim. Search snippets, syndicated copies, and copied press releases may be relevant, but they are not independent confirmation. Record inaccessible pages instead of accepting a title as evidence.
| Label | Use when | Required note |
|---|---|---|
| Direct support | The passage states the material proposition | Exact supporting span and preserved scope |
| Partial support | Only part of a compound claim is supported | Unsupported words or missing qualification |
| Context | The passage supplies background but not proof | Where factual support must come from |
| Contradiction | The passage conflicts with the claim | Temporal, scoped, or substantive conflict |
| Duplicate context | The object repeats another source owner or syndication cluster | Canonical object ID and cluster |
| Unverifiable | The source or passage cannot be checked | Access failure and evidence still needed |
Separate retrieval, context, and generation
A strong evidence object can be omitted or truncated before generation. A weak answer can result from retrieval, context assembly, prompt instructions, the model, rendering, or citation placement. Preserve each layer so a failure has an owner.
- Retrieval: raw objects, order, filters, timestamps, errors, and zero-object results.
- Context assembly: selected object IDs, deduplication, ordering, character or token limits, and truncation.
- Generation: model and version, prompt, raw answer, rendered answer, citations, retries, and safety behavior.
- Evaluation: claim map, reviewer labels, disagreement, calculation, and final decision.
Do not calculate “citation accuracy” from only the successful answer rows. Include timeouts, errors, empty evidence sets, inaccessible sources, and invalid responses in the declared denominator.
Deduplicate by source owner and claim
Several passages from one page can improve coverage without creating independent corroboration. Several domains can reproduce one press release. Track object count, unique canonical pages, unique source owners, and syndication clusters separately.
Negative evidence also matters. Record an authoritative current source that the system did not retrieve, a decisive limitation missing from an otherwise relevant passage, or a canonical mismatch. Retrieval recall cannot be estimated from returned objects alone; it needs a declared reference set for the query.
Treat multimodal evidence as more than a thumbnail
For image and video objects, verify the landing page, media owner, surrounding text, publication date, and whether the returned passage describes the media or only nearby copy. A thumbnail does not prove what appears in the full media. Record unavailable transcripts, changed captions, region restrictions, and rights boundaries.
If the application extracts facts from a chart or frame, keep that extraction as a separate observation with its method and reviewer. Do not present a conceptual image, generated caption, or nearby article text as direct evidence from the media itself.
Reproduce vendor benchmarks only with a declared contract
Microsoft reports grounding satisfaction on 3,000 global, blind queries sampled from production with configurations including 10 results and 10,000 characters per result. It also reports sub-165 ms p95 latency and roughly 2.5× faster performance than the next alternative in its cohort, measured from virtual machines in five data-center regions with unique queries to avoid cache hits.
Those details improve attribution but do not expose the complete query set, competitor identities, scoring rubric, traffic mix, failure treatment, or every environment control. The safe wording is “Microsoft reports.” A reproduction needs its own sample, geography, account tier, API version, network location, concurrency, cache rule, timeout, retry policy, comparator configuration, and reviewer rubric.
| Measure | Numerator | Denominator | Boundary |
|---|---|---|---|
| Claim coverage | Material claims with at least one object | All material claims | Presence is not entailment |
| Direct support | Claims directly supported after review | Claims evaluated | Reviewer judgment needs a passage |
| Primary-source rate | Directly supported claims using closest owner | Directly supported claims | Not every question has an official source |
| Freshness pass | Objects meeting a predefined date rule | Objects where freshness matters | Rule must be set before review |
| Reliability | Complete valid responses | All attempted requests | Keep timeouts and empty sets |
| Latency | Measured distribution | All declared attempts | Report median, p95, and failures |
Download the evidence-object scorecard
The CSV below joins the raw object, resolved source, passage hash, claim relationship, source ownership, freshness rule, context-selection state, answer use, latency, error, reviewers, and limitation. Its sample rows begin with EXAMPLE-REMOVE; delete them before adding a real run.
Download the Microsoft Web IQ evidence-object scorecard (CSV)
Keep raw response files beside the scorecard under an access policy appropriate to the content. The citation absorption audit provides compatible claim-to-passage labels, and the tool-score guide helps expose weights instead of hiding them in one number.
Release gates for an evaluation
- The exact Web IQ product surface, access state, version, region, and date are recorded.
- Every published percentage has a numerator, denominator, and missing-data rule.
- Vendor claims are attributed and visually separated from reproduced results.
- Raw evidence objects and selected context can be reconstructed without credentials in the public artifact.
- Zero-object responses, errors, timeouts, and inaccessible sources remain in scope.
- Two reviewers adjudicate ambiguous support labels or the report states that only one reviewer was used.
- No evidence object, citation, or latency result is converted into a consumer search-ranking claim.
Limits and re-audit triggers
Search Engine Answer has not received or run a Web IQ account for this article and has not reproduced Microsoft’s benchmark. Public documentation may not expose the response schema available to a particular customer. The method therefore defines the evidence required for a pilot; it does not certify product quality.
Start a new run when access terms, API version, region, retrieval configuration, evidence schema, passage size, query set, comparator, model, context limit, scoring guide, or source corpus changes. Preserve prior runs as dated observations. Web content can change after retrieval, so retain the canonical URL, retrieved passage or permitted hash, and review time together.
Primary sources
- Microsoft Bing: Announcing Microsoft Web IQ — product positioning, architecture, evidence-object description, publisher-control statement, and benchmark claims.
- Microsoft Command Line: Grounding at scale — semantic-first retrieval, passage-level evidence, provenance, token economics, and systems context.
- Microsoft IQ documentation — current product-family distinction and Web IQ description.
Source check: August 31, 2026. Reconfirm access, schema, benchmark wording, and product boundaries before every evaluation.
Keep learning
Continue this topic
Next in this topic
Cloudflare Redirects for AI Training: Test Canonicals Before Turning 301s On
Earlier in this topic
Cloudflare Pay Per Use: Build a 31-Field Pilot Ledger
AEO & AI Search
Ask a question or join the discussion