How to Test Gemini 3.7 Flash Before Switching Grounded Answers
Test Gemini 3.7 Flash with frozen tasks, claim-level citation checks, tool and schema failures, accepted-task economics, reviewer agreement and a canary rollback rule.
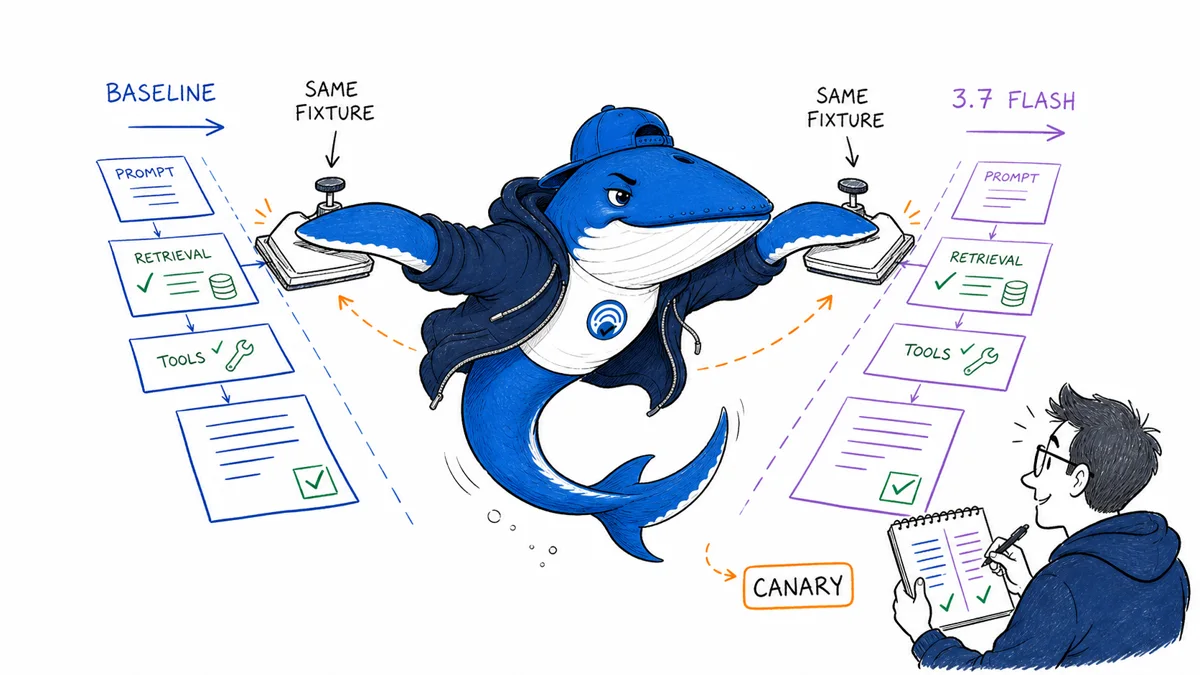
Google now routes requests for gemini-3.7-flash to gemini-3.8-flash, according to its October 8 release notes. This page retains the earlier migration protocol, but a new request using the 3.7 identifier no longer supplies an independent 3.7 baseline.
Google released Gemini 3.7 Flash on August 13, 2026. Treat its earlier capability description as historical context. Evaluate the currently served model and its returned identity; compare against archived 3.7 outputs only when their original capture and configuration are documented.
Start with what Google actually documents
The current deprecation table lists the replacement and no announced shutdown date for the legacy Flash identifier. Automatic routing and a future shutdown are different states. Use the current 3.8 model documentation for the configuration being served, not an old capability list as proof of an available frozen model.
That is the documented capability layer. It is not an observed invocation, an accepted answer or a measured business result. Keep those evidence layers separate throughout the migration.
Archive comparisons need a dated boundary
If an archived response was captured before routing changed, keep its capture date and source versions. Comparing it with a current answer also changes the retrieval date, so a newly available source can explain a difference independently of the model. Report this as a historical comparison unless a controlled design isolates the change.
For the active evaluation, use the 3.8 grounded-answer protocol. The separate Deep Research agent retirement concerns an agent identifier and its scheduled shutdown, not the Flash routing rule.
Freeze reader jobs before looking at candidate output
A useful fixture resembles production. Include stable facts, recent product facts, ambiguous questions, multi-source synthesis, a zero-result case, a tool failure, a malformed input and at least one prompt where the responsible answer is uncertainty. Record the expected answer boundary rather than writing a single preferred sentence.
Freeze the fixture and rubric before the first current-model evaluation. Otherwise a fluent candidate answer can quietly change what reviewers count as success. The downloadable fixture below marks its first row EXAMPLE-REMOVE because SearchEngineAnswer has not run this comparison for you.
Hold the surrounding stack constant
| Layer | Freeze inside a pair | Record as observed |
|---|---|---|
| Input | Prompt, files, locale and date | Acceptance, truncation and safety response |
| Retrieval | Grounding configuration and query policy | Queries, sources, timestamps and missing coverage |
| Tools | Definitions, permissions and result fixtures | Selection, arguments, sequence, errors and recovery |
| Output | Schema and rendering rules | Raw answer, parsed value and validation error |
| Operations | Retry, timeout and traffic class | Latency, usage, billed dimensions and failures |
Save both the requested identifier and any returned model identity or routing evidence. An explicit identifier is not sufficient version control when the provider redirects it. Keep the API surface, SDK version and configuration beside every run. Archived 3.7 responses can be a historical reference, but a fresh 3.7-versus-3.8 request pair is not a two-model experiment under the current routing.
Audit factual support claim by claim
- Split the answer into material facts, interpretations and recommendations.
- Map each factual claim to the nearest returned grounding evidence.
- Open the source and locate the passage that supports, qualifies or contradicts the claim.
- Classify support as direct, qualified, conflicting, absent or inaccessible.
- Record uncited material claims and citations that do not support the nearby sentence.
- Repeat time-sensitive fixtures and preserve disagreement across runs.
A citation count is not a quality score. Five links can repeat one announcement or miss the material claim; one current primary document can be enough for a narrow product fact. The Gemini citation-span audit explains how to keep answer text, grounding chunks and display links distinct.
Preserve grounding before rendering it
Google’s Grounding with Google Search documentation describes response metadata used to connect generated text, search queries and source material. Store the raw response before transforming it for a user interface. A renderer can appear correct while dropping a citation segment, changing a link or collapsing several sources into one untraceable label.
| Evidence layer | Question it answers | What it cannot prove alone |
|---|---|---|
| Search query record | What retrieval was attempted? | That a returned source supports the claim |
| Grounding source | Which document was returned? | That the relevant passage was used correctly |
| Text mapping | Which answer span points to evidence? | That every material claim is covered |
| Rendered citation | What the reader can open | That the underlying URL and label survived transformation |
Treat tools and structured output as failure paths
Supported function calling does not mean the candidate will select the same tool, pass valid arguments or recover from the same error. Run deterministic tool fixtures where possible. Record skipped calls, duplicate calls, order changes, malformed arguments, permission denials, timeouts and the answer produced after a failure.
Validate structured output against the production schema, not visual appearance. Preserve the raw candidate response when parsing fails. A valid JSON object can still violate a semantic rule, while a useful answer can fail because the integration changed a field name or accepted a value that the downstream system rejects.
Measure latency and cost per accepted task
Record first-token time, total latency, retries, input and output usage, grounding or tool charges where applicable, and the number of tasks that pass the declared rubric. Report median and tail latency by task class; one global average can hide a slow or unreliable workflow.
Do not budget a redirected request from an earlier introductory-price announcement. Reopen the current pricing page for the model and API route actually being served when the test runs and again before a production cutover. The useful denominator is cost per accepted task, not cost per API response.
Declare the release rule before the canary
| Decision | Trigger | Required record |
|---|---|---|
| Proceed | No critical regression; task acceptance and cost remain inside declared bounds | Frozen comparison report and named approver |
| Hold | Mixed quality, low sample or an untested tool path | Open issue, owner and retest date |
| Rollback | Critical citation, safety, schema or tool failure exceeds its threshold | Routing change, incident evidence and preserved prior configuration |
Begin with internal traffic or a small canary and monitor by task class. Verify that any fallback is independently available; changing the identifier back to 3.7 does not restore the old model under automatic routing. Use an available accepted alternative or pause the affected workflow when critical checks fail.
Review enough disagreements to trust the rubric
Have two reviewers independently classify a meaningful subset before one person scores the full fixture. Compare disagreements on claim boundaries, direct support, source quality and critical-failure status. If reviewers cannot apply the rule consistently, refine the rubric and rescore the affected rows rather than averaging incompatible judgments.
Record the sample size and reviewer assignment. A migration can look better simply because the candidate’s fluent wording makes unsupported claims harder to notice. Preserve the raw answer and cited passage so a later reviewer can reconstruct the decision.
Download the migration fixture
Download the Gemini 3.7 grounded-answer migration fixture (CSV). Replace the example row before use. Keep secrets, personal data and full private prompts out of shared artifacts; use safe references when a production input cannot be copied.
The fixture keeps configuration, grounding, claim support, tool behavior, format, latency, usage, reviewer decision and limitation fields together without compressing them into one score.
What this method does not establish
SearchEngineAnswer has not run Gemini 3.7 Flash against a declared grounded-answer sample, so this page does not claim higher accuracy, better citations, lower cost or faster latency. The CSV is a test design, not measured research. Results from one prompt set, locale, account, date or retrieval configuration should not be generalized beyond that scope.
For broader evaluation discipline, use the layered tool-score guide and the evidence-led publication gate.
Primary documentation
Keep learning
Continue this topic
Next in this topic
Citation Wars: Can GEO Optimization Make Content Worse?
Earlier in this topic
ChatGPT-User and robots.txt: What You Can—and Cannot—Block
AEO & AI Search
Ask a question or join the discussion