Mistral Search Toolkit: Build a 32-Field Retrieval Release Gate
Freeze the toolkit, corpus, document identities, queries, candidates and reranking before evaluating generation with a 32-field release ledger.
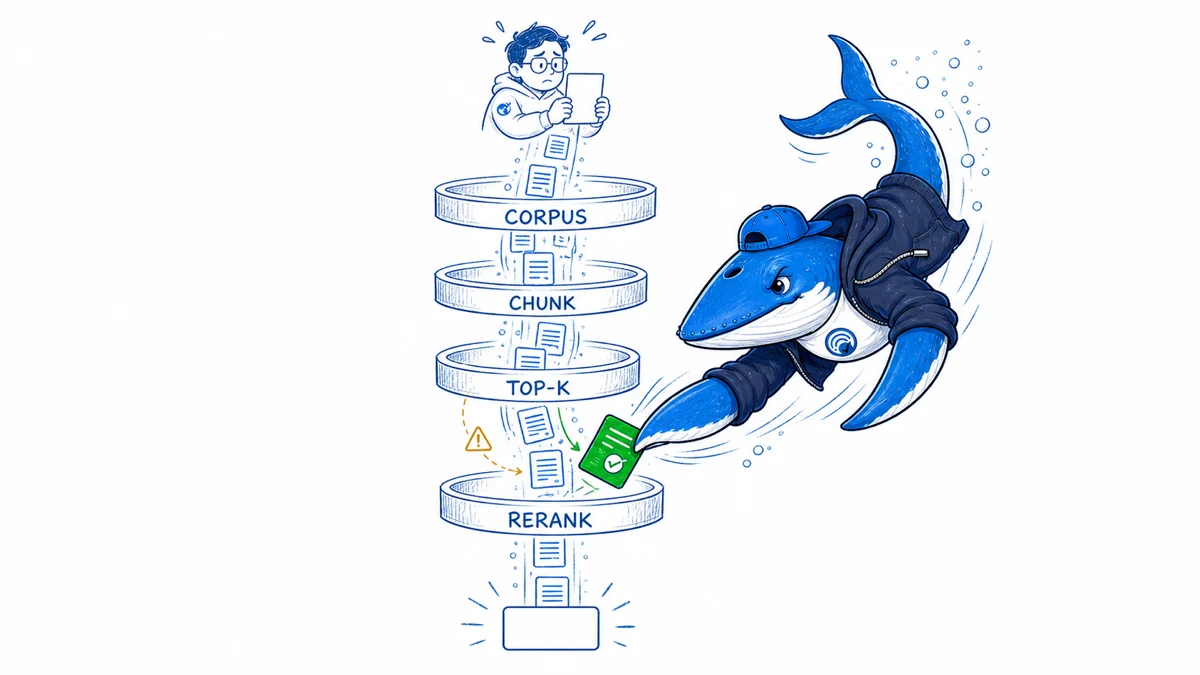
Direct answer: evaluate Mistral Search Toolkit as a versioned retrieval pipeline before blaming the language model that consumes its results. The current framework separates ingestion, document identity, chunking, indexing, query preprocessing, retrieval and reranking. A weak generated answer can begin with a missing file, an extraction error, an unstable chunk ID, a poor candidate set or a reranker that demotes the decisive passage.
This guide turns that pipeline into a release gate. It uses current Mistral documentation retrieved August 29, 2026, including the unified Document/DocumentChunk identity model and the 0.0.9 changelog. The downloadable 32-field retrieval release ledger is a template, not a completed benchmark.
Freeze the toolkit version and release contract
Mistral announced Search Toolkit in public preview on May 28, 2026. Its current Search Toolkit documentation describes a Python framework for ingestion, retrieval and evaluation whose components can be replaced. The current changelog lists 0.0.9 breaking changes and labels 0.0.8 as the initial tech-preview release.
Record the package version, Python version, backend, schema, embedding model and every optional component. Do not call two runs comparable when one uses a deprecated index model or different identity contract. Preview software can change, so every release result needs a retrieval date and a configuration fingerprint.
| Layer | Evidence to save | Failure it can expose |
|---|---|---|
| Ingestion | Source manifest, extractor, chunker, warnings and rejected files | Missing or malformed evidence |
| Index | Schema version, indexing mode, backend and document count | Stale or incompatible records |
| Retrieval | Original query, processed query, top-k, filters, ranked IDs and scores | Relevant chunks never enter the candidate set |
| Reranking | Candidate order, reranker version, final order and scores | A decisive passage is demoted or removed |
| Generation | Frozen context, prompt, model and answer assessment | The model misuses adequate retrieved evidence |
Build a corpus manifest before measuring search quality
Give every source a stable source_id, owner, path or URL, content hash, language, MIME type, permission state and expected extraction result. Preserve rejected documents and ingestion errors. A benchmark that silently excludes scanned PDFs, spreadsheets or difficult layouts can overstate quality.
Sample extracted text against the source. Check headings, tables, lists, page boundaries, links, non-English characters and repeated navigation. Record the extractor and optional package used. Mistral’s current docs list format-specific extractors and splitters; availability alone does not prove that a chosen extractor preserved the evidence your queries require.
Use the current document identity model
The document-model documentation says Document and DocumentChunk derive deterministic identities from source_id and a locator. Search results carry the same id, source_id, locator, parent_ref and chunk_type contract. This makes a returned chunk traceable to the ingested source.
Version changes matter. The 0.0.9 changelog removed the earlier separate page representation and recommends DOCUMENT_PER_CHUNK over the deprecated single-document model. Store the identity fields with every judged result and migrate old baselines explicitly rather than comparing IDs that came from different contracts.
| Field | Role | Review check |
|---|---|---|
source_id |
Stable identity for the ingested source | Maps to one versioned manifest record |
locator |
Position such as character or page-and-character range | Reconstructs the judged passage |
id |
Deterministic chunk identity | Remains stable only under the documented identity inputs |
parent_ref |
Reference back to the document | Resolves without an orphaned source |
chunk_type |
Distinguishes content, image annotation or summary | Prevents generated summaries from being judged as source text |
Define queries and relevance before comparing configurations
Create a fixed query set that covers exact names, paraphrases, identifiers, multi-constraint questions and no-answer cases. Label relevance before viewing configuration scores. State whether a judgment applies to a document, chunk or passage, and use a second reviewer for ambiguous examples.
Include difficult and business-critical cases, not just prompts that retrieve obvious wording. Preserve disagreements and the adjudication rule. A release gate should stop when a critical class fails even if the mean across easier queries improves.
Compare candidate generation before reranking
The current documentation highlights vector retrieval and optional reranking. Mistral’s announcement also describes sparse BM25 and hybrid configurations, while the Vespa search-index documentation exposes BM25 fields for hybrid ranking. Record the implemented retriever and backend rather than assuming every advertised strategy is active in your configuration.
Run the same corpus, queries, filters and cutoff across configurations. Save ranked chunk IDs and scores before reranking. If a relevant chunk never enters the candidate pool, changing the generator cannot recover it. If the candidate exists but ranks too low, retrieval settings, chunking or ranking need attention.
Test query preprocessing as its own intervention
Search Toolkit documents LLM query rewriting and extension. These can improve semantic coverage, but they can also drop an identifier, broaden a constraint or change an entity. Store the original and processed query, the preprocessor class, model and configuration for every run.
Compare retrieval with and without preprocessing against the same judgments. Do not describe a rewritten query as the user’s words. If preprocessing introduces sensitive text or changes the meaning, treat that as a release failure even when aggregate recall rises.
Measure reranking without hiding lost evidence
Mistral lists LLM, cross-encoder and reciprocal-rank-fusion rerankers. Save the entire input candidate set, original order, reranked order, cutoff and component version. A reranker can improve the first relevant result while removing another passage needed for a complete answer.
Review both movement and survival. Record whether decisive chunks move up, remain below the context cutoff or disappear. Evaluate critical query classes separately; an average gain cannot excuse systematic loss in safety, policy or product-constraint questions.
| Metric | Use when | Required declaration | Limit |
|---|---|---|---|
| Recall@k | All relevant evidence should enter the candidate set | Relevance unit, k and number of relevant items | Does not reward ordering within k |
| Precision@k | Context capacity or review cost is constrained | Relevance rule, k and denominator | Can penalize useful supporting evidence under a narrow label |
| MRR | The first relevant result is the main task | Query count and treatment of no-result queries | Ignores later relevant results |
| NDCG@k | Relevance is graded and order matters | Gain scale, discount formula and k | Sensitive to judgment design |
Choose metrics that match the reader decision
Mistral’s announcement names recall, precision, MRR and NDCG as built-in evaluation metrics. Define the metric formula, cutoff, judgment unit and denominator in the release record. Do not combine them into an unexplained quality score.
Set thresholds before viewing the new run. Include guardrails for no-answer behavior, critical query classes, latency and errors. A change can pass recall and still fail because it returns sensitive or unauthorized content; retrieval quality and authorization are adjacent control planes.
Freeze retrieved evidence before testing generation
Once retrieval passes, freeze the selected chunks and test generation separately. Preserve context order, truncation, prompt, model, temperature or sampling settings and output. Score claim support, completeness, contradiction handling and abstention against the frozen evidence.
This split identifies the repairable layer. If relevant evidence is absent, fix ingestion or retrieval. If evidence is present and the answer misstates it, investigate context assembly or generation. The retrieval-provenance guide provides a related contract for external search tools.
Use the 32-field retrieval release ledger
The CSV’s unit of analysis is one query under one frozen configuration. It records corpus and toolkit versions, identity fields, preprocessing, candidates, reranking, metrics, critical-class status and the release decision. Rows marked EXAMPLE-REMOVE are illustrative and are not Mistral performance results.
Keep source documents, raw passages and private queries in the appropriate restricted store. The public artifact should not include credentials, personal data, confidential documents or proprietary prompt content. Store safe references and aggregate decisions instead.
Stop the release when the evidence contract breaks
Hold a release when a source disappears without explanation, an identity cannot resolve, critical-query recall falls below the declared threshold, preprocessing changes an entity, reranking drops decisive evidence, or the benchmark cannot be reproduced from its configuration. A package upgrade is not a reason to waive those checks.
SearchEngineAnswer has not run a comparative Search Toolkit benchmark for this page. This is a method for building one. Use the evidence-led publishing guide for the final claim review, and attribute Mistral’s production or customer-performance statements until they are independently reproduced.
Update note: This page was rebuilt on August 29, 2026 to follow the current Studio Search Toolkit documentation and 0.0.9 identity model. Preview behavior, component names and examples may change after the retrieval date.
Keep learning
Continue this topic
Next in this topic
Cloudflare Content Format Chart: What 25 Requests Actually Returned
Earlier in this topic
Cloudflare Crawl-to-Referral Ratios: A Defensible Audit Method
Research
Ask a question or join the discussion