CITECHOICE Finds Structure Shifted Citation Credit, Not Source Admission
A causal replay found that structured rendering increased citation count, while its effect on whether a source was cited at all remained inconclusive.
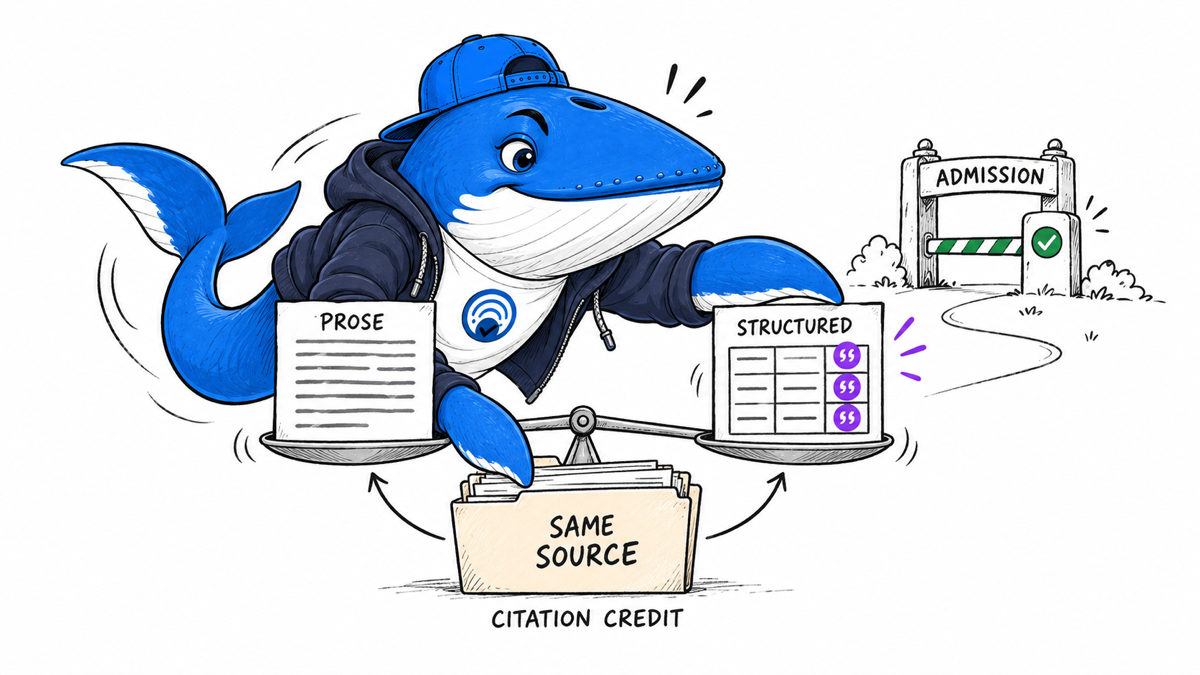
Structured presentation changed how much citation credit a source received after retrieval, but it did not establish that structured pages enter the answer more often. That is the useful distinction in CITECHOICE, a causal audit of source presentation in agentic search.
The reported experiment found an average increase of 0.50 citations per answer when a target document was rendered in a structured format instead of prose. The estimated increase in whether the target appeared at least once was smaller and statistically inconclusive. Publishers should read this as a presentation effect inside a controlled source set, not as proof that tables or schema improve retrieval.
The experiment isolates a question most citation studies mix together
AI-search visibility contains several decisions. A system may decide to browse, retrieve a page, include it in context, use its claims, cite it, or cite it several times. Observational studies often see only the final citation and attribute the whole chain to page format or source rank.
CITECHOICE narrows the question: when the underlying source pair is held constant, does changing presentation or order redistribute visible citation credit? The authors assembled 129 everyday-query transcripts and 113 same-call source pairs. Blinded human review confirmed 103 of those pairs as comparable enough for the controlled replay.
The design matters because it does not compare unrelated pages that happen to use different layouts. It replays the same evidence under crossed conditions, changing document order and rendering while preserving the underlying source content.
A 2×2 replay separates order from rendering
Each source pair can be tested in four cells: target first or later, and target rendered as structured content or prose. Hash verification helps confirm that the intended evidence survives the transformation. That gives the experiment a cleaner counterfactual than comparing a ranked page with a different lower-ranked page.
| Target order | Presentation | Question answered |
|---|---|---|
| Earlier | Structured | What happens when both potential advantages are present? |
| Earlier | Prose | What remains when order is favorable but rendering is plain? |
| Later | Structured | Can presentation change credit when order is less favorable? |
| Later | Prose | What is the comparison state for both treatments? |
This is a citation-allocation experiment. It does not reproduce the earlier retrieval stage that chose these documents, and it does not show how often a page would be admitted from the open web.
Structured rendering increased citation count by 0.50 per answer
The paper reports a treatment effect of +0.50 target citations per answer for structured rendering, with a 95% confidence interval from +0.20 to +0.84 and a Holm-adjusted p value of 0.033.
The effect on citation incidence, meaning whether the target received at least one citation, was +4.5 percentage points. Its confidence interval ran from -1.4 to +10.4 percentage points, with p = 0.168. That interval crosses zero, so the experiment does not establish a reliable admission effect.
| Measure | Reported effect | Safe interpretation |
|---|---|---|
| Citation count | +0.50 citations per answer | Once the source was in the controlled context, structured rendering redistributed visible credit. |
| Citation incidence | +4.5 percentage points | The estimate is compatible with a small loss, no effect, or a gain. |
| Fresh-decoding changes | 15% of binary citation decisions | A single generation is too noisy to support a strong page-level conclusion. |
The apparent rank advantage shrank under controlled reordering
The observational data showed a 42.3 percentage-point citation gap between sources at rank one and rank five. In the controlled main replay, reordering produced a 7.9-point effect. In the held-out replay, the reported effect was zero.
This does not prove that source order never matters. It shows why an observed rank gap should not automatically be read as a causal position effect. Higher-ranked sources can differ in authority, content, relevance, accessibility and presentation before order is considered.
The same warning applies to publisher audits. If one cited page has a comparison table and another does not, the table may be associated with the citation without causing retrieval, selection or support.
Format for comprehension, then test citation allocation separately
The result supports a restrained publishing decision. Use structure when it makes the claim, unit, relationship or limitation easier to inspect. A small table can separate products and prices. A definition list can keep terms beside meanings. A short procedure can expose order and stopping conditions.
Do not fragment prose into decorative cards solely to chase AI citations. CITECHOICE does not establish that a structured page will be crawled, retrieved, trusted or admitted more often. It also does not show that adding schema markup produces the reported rendering treatment.
For a broader model of the citation pipeline, compare this result with the five-stage agentic search lifecycle and the citation-selection model. Those pages keep search invocation, retrieval, use and citation as separate observables.
Run a paired presentation test without changing the evidence
- Select a question and two passages that support the same answer at comparable depth.
- Create a prose rendering and a structured rendering without adding claims, removing caveats or changing numbers.
- Hash or archive each input so the tested evidence can be inspected later.
- Cross presentation with order, producing four conditions rather than one preferred prompt.
- Repeat each condition under the same model, settings and retrieval state.
- Record citation incidence, citation count, claim support and output variation separately.
- Report paired differences and uncertainty. Do not promote a one-run winner.
Download the CITECHOICE reproduction ledger. The rows are marked EXAMPLE-REMOVE and demonstrate the test shape only. They are not SearchEngineAnswer measurements.
What this experiment does not isolate: presentation sits downstream of retrieval and page exposure. The four-layer citation failure map shows where CITECHOICE fits, and why a change in citation credit should not be reported as proof that a source entered the candidate set more often.
The practical conclusion is narrower and more useful
CITECHOICE provides causal evidence that document presentation can change how citation credit is distributed within a controlled context. It does not prove that structured content enters that context more often.
That boundary prevents a familiar SEO mistake: turning a measured downstream effect into an unsupported upstream ranking rule. Improve structure because readers can inspect the evidence, then measure retrieval and citation as separate stages.
Keep learning
Continue this topic
Next in this topic
CiteShade Raised Wrong Answers From 1% to 68%
Earlier in this topic
Generative Search Ads Split Relevance, CTR and Revenue
Research
Ask a question or join the discussion