A GEO Measurement Paper Links AI Visibility to Business Impact, but Tests Simulated Answers
A new GMMM preprint connects generated-answer inclusion, question volume, system use and notice probability, but its empirical demonstration is simulated.
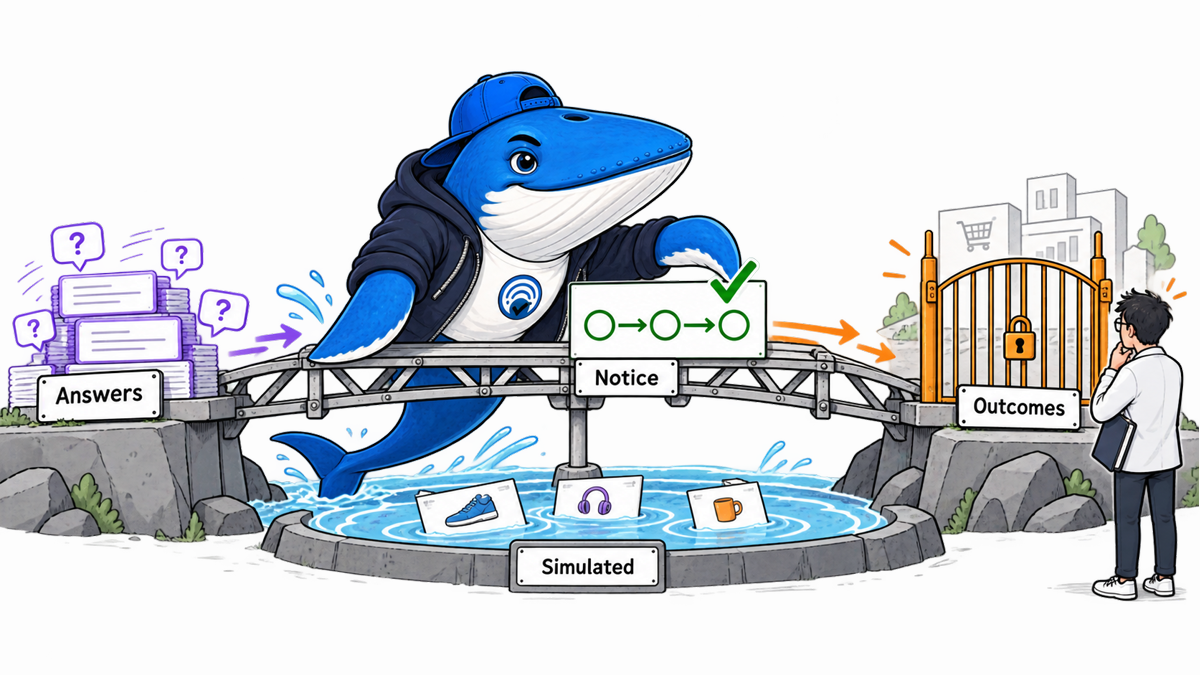
A new preprint proposes a way to connect visibility in generated answers with business outcomes, but its empirical demonstration uses simulated product recommendations. The work is valuable as a measurement design. It is not evidence that higher GEO visibility has already caused sales in a live answer engine.
The useful idea is not a new visibility score. It is a causal bridge: generated answers affect whether a brand is noticed, and notice can affect an outcome. Every link in that chain needs its own data and uncertainty.
The attribution problem the paper tries to solve
Traditional marketing-mix models usually work with exposures such as spend, impressions or reach over time. Generative answer systems create a different surface. A brand can be named without a link, cited without being noticed, recommended in different positions, or omitted as prompts and systems change.
The preprint, titled Generative Marketing Mix Modeling, introduces GMMM for generative engine optimization and GEM for sponsored placements. It combines repeated answer observations, question volume, system-use shares and notice probabilities, then relates estimated exposure to an outcome model.
The proposed chain has four distinct quantities
| Quantity | What it represents | Evidence needed |
|---|---|---|
| Answer inclusion | How often a brand, product or source appears in repeated generated answers. | Frozen prompts, system state, answers, dates and completed-row denominator. |
| Question volume | How often people ask a relevant class of questions. | Platform or panel estimate with geography, period and sampling method. |
| System-use share | How much of the relevant audience uses each answer system. | Comparable market-use estimates, not a mixture of visits and users. |
| Notice probability | The chance that an included item is actually seen or remembered. | Position-aware experiments, panels or clearly labeled assumptions. |
Multiplying uncertain estimates does not remove uncertainty. A defensible implementation would preserve distributions or sensitivity ranges, show the contribution of each input and keep modeled exposure separate from observed referrals.
GEO and sponsored placements require different treatment
For organic generative engine optimization, inclusion depends on the prompt, model, retrieval and response. For generative engine marketing, the paper adds sponsored placement and disclosure or notice. That distinction matters because a paid placement can have a contractually defined eligible audience while organic inclusion must be sampled from a changing answer system.
Neither route can be represented honestly by “share of AI.” A system might mention a brand frequently but place it late in an answer. A sponsored item might be served but not noticed. A cited page might receive no detectable referral even if the answer influenced later branded search or direct navigation.
What the empirical section actually demonstrates
The authors simulate English and Japanese product-recommendation environments to show how the framework behaves. Simulation is appropriate for illustrating model mechanics and identification assumptions. It cannot establish the size of a real-world GEO effect because the answer observations, notice process and outcomes are generated under the study design.
The paper was submitted to arXiv on September 10, 2026. It is a preprint, not a completed field experiment and not proof of deployment by Google, OpenAI, Microsoft, Perplexity or another platform.
Do not publish the simulation as a performance benchmark. It does not tell a merchant that a one-point visibility increase will produce a specific sales lift. It shows how a researcher might structure the question and test sensitivity.
Where causal claims can break
- Demand moves both variables. A product launch can increase questions, mentions and sales at the same time.
- Prompt samples drift. Replacing a prompt set changes the measured exposure even if the platform does not change.
- Notice is not inclusion. An answer appearance may be below the fold, ignored or misunderstood.
- Systems are not interchangeable. Usage share, prompt mix, citations and user tasks differ by product.
- Referral logs are incomplete. Apps, privacy controls and later direct visits can hide an influenced journey.
- Marketing overlaps. Search ads, email, PR, retail distribution and seasonality can affect the same outcome.
A field blueprint for publishers and brands
- Define the outcome first. Choose qualified leads, orders, subscriptions or another business event with a stable definition.
- Freeze a stratified prompt panel. Preserve task, market, language and commercial stage instead of collecting only prompts where the brand appears.
- Repeat observations. Save completed and failed runs, answer position, mention, citation, linked URL and model or mode when available.
- Estimate notice independently. Use a small user test or a disclosed range rather than assuming every inclusion is viewed.
- Maintain separate journey signals. Keep AI referrals, direct landings, branded search, self-reported discovery and conversions in different columns.
- Use a credible comparison. A phased content change, unaffected prompt group or market-level holdout is stronger than a sitewide before-and-after chart.
- Run sensitivity checks. Recalculate results under lower and higher notice, question-volume and usage-share assumptions.
A worked example that stays honest
Suppose a fixed panel contains 100 purchase-research prompts and 90 complete. A brand appears in 18 completed answers. The observed inclusion rate is 18 of 90, or 20%, for that prompt panel and period. If a separate study estimates that similar placements are noticed between 30% and 50% of the time, modeled noticed exposures should be reported as a range, not as 18 certain impressions.
If orders rise during the same period, the increase is not automatically caused by the answer appearances. The team should test whether the change remains after accounting for price, promotions, search demand, distribution and other marketing. The observation can prioritize an experiment; it cannot substitute for one.
What this changes for AI visibility reporting
The paper strengthens the case for moving beyond mention counts, but it also raises the evidence bar. A useful report needs denominators, repeated observations, visibility position, platform shares, notice assumptions and a defined business outcome. It should show which values are observed, estimated or simulated.
That complements our four-ledger AI visibility framework, which keeps mentions, citations, referrals and revenue separate. GMMM describes a possible bridge between those ledgers. The bridge should remain inspectable rather than becoming another opaque composite score.
Our verdict
This is a promising research framework and a poor shortcut. It gives teams a vocabulary for modeling generative exposure without pretending a citation equals revenue. Its simulated demonstration cannot validate a commercial lift, and the hardest real-world inputs, especially question volume and notice probability, remain difficult to obtain.
The next high-value evidence would be a preregistered field experiment with frozen prompts, observable content or placement changes, independent notice measurement and a business outcome. Until then, use the framework to design better tests, not to manufacture ROI precision.
Keep learning
Continue this topic
Next in this topic
ChatGPT, Claude, Grok and DeepSeek Search the Web Differently
Earlier in this topic
Chrome Now Measures Ad Count, Density and Weight in CrUX
Research
Ask a question or join the discussion