
← Tool directory
Source documentation ↗
TOOL PROFILE
Courlan
Filter and normalize candidate URLs before a crawl or content extraction run.
Open source
Community support
0 upvotesSign in to upvote
Upvotes come from SearchEngineAnswer members. GitHub stars and reader reviews are counted separately.
Claim this tool if you maintain it.
- Best for
- Crawling
- Setup required
- Python and pip. Use a virtual environment for reproducible runs.
- Costs to check
- The library runs locally. Budget for pipeline integration and testing.
- License in catalog
- Apache-2.0
Project screenshot
GitHub repository
- GitHub stars
- 179
- Forks
- 17
- Last push
- 2026-11-06
- Primary language
- Python
GitHub snapshot from . Stars count GitHub bookmarks. Reader ratings appear separately below.
How to install Courlan
- Create a Python virtual environment and install Courlan with pip install courlan.
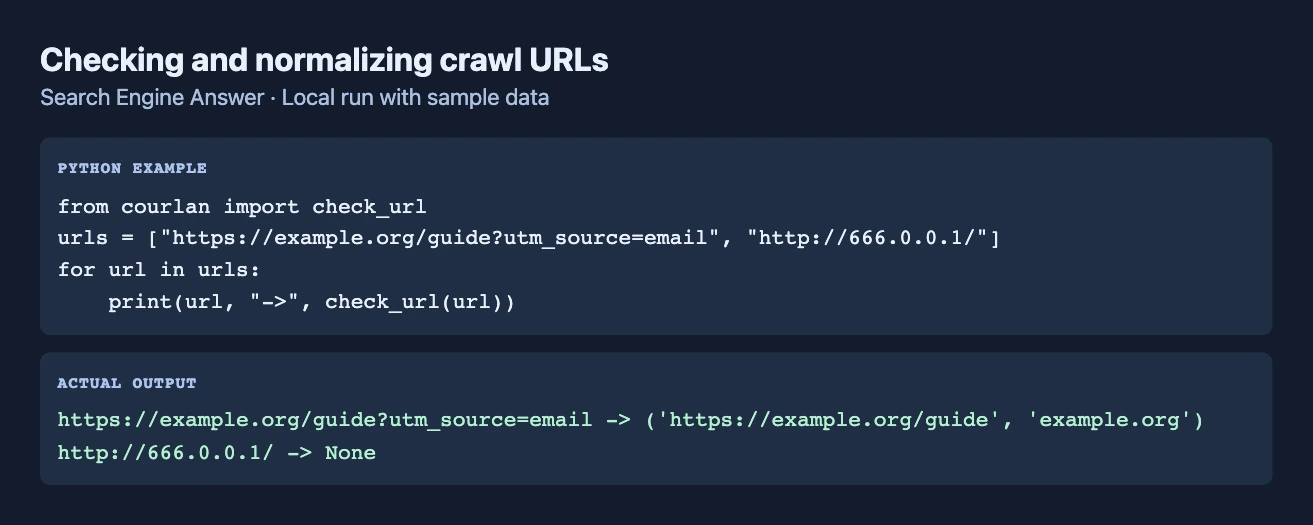
- Import the documented check_url function and assemble a short list of example URL variants.
First tutorial for Courlan
- Compare checker results for URLs with tracking parameters and for URLs that select different content.
- Review the returned cleaned URLs and preserve any variants your application treats as distinct pages.
Where Courlan fits
Use it to reduce duplicate-looking URLs before sending a list to a crawler.
- When to choose another tool
- Inspect server redirects and canonical tags when determining whether two URLs represent the same public page.
- First evaluation
- Run the URL checker against several URL variants from a site with known handling of query parameters.
- How to interpret the result
- A normalized URL is a heuristic output. Preserve query parameters that actually select different content.
Reviews and discussion
Reader reviews
Be the first to share your experience with this tool.
Discussion
Ask a question or share a setup tip.
Flag an outdated detail
Include the field that needs updating and a source link. Copy your draft, then use the corrections policy to contact the editorial team.
Write a review or join the discussion