Google before: Filter: Build a 29-Field Temporal Leakage Audit
Use date-filtered search to find candidates, then inspect snapshots, page updates, related modules, metadata conflicts and leakage severity before admitting evidence.
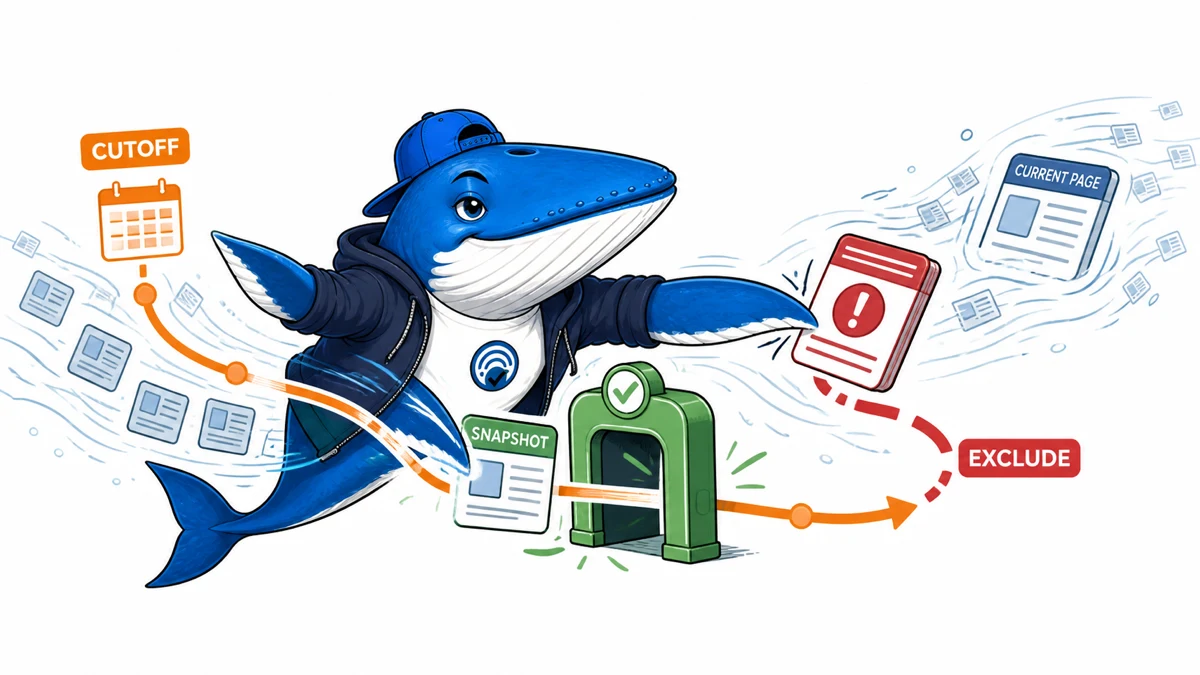
Direct answer: treat Google’s before: operator as a way to find candidate URLs, not as proof that a page contains only information available before the cutoff. A July 2026 ACL paper found major post-cutoff information in at least one Google result for 71% of 393 retrospective forecasting questions. The practical fix is to inspect the retrieved page state, compare a dated snapshot and record a leakage decision before the document enters an evaluation corpus.
This guide turns that boundary into a 29-field audit. It does not repeat the ACL experiment or claim that every historical Google search leaks. The downloadable temporal-leakage audit ledger contains two rows marked EXAMPLE-REMOVE; replace them with your own observations.
What the ACL study actually measured
El Lahib and colleagues tested retrospective forecasting, where a system answers resolved questions while pretending it only knows information available at the question’s opening date. They generated 10 to 20 queries per question, retrieved about 100 unique URLs per question and audited 38,879 Google URLs across 393 questions. The Google collection ran in late December 2025, according to the authors’ public audit repository.
| Measure | DuckDuckGo | |
|---|---|---|
| Questions evaluated | 393 | 389 |
| URLs fetched | 38,879 | 34,454 |
| URLs with post-cutoff information | 33.2% (12,903) | 34.5% (11,898) |
| Questions with at least one major leak | 71.0% | 81.2% |
| Questions with a direct answer leak | 41.0% | 54.8% |
Those are paper results, not SearchEngineAnswer measurements. They apply to the engines, query construction, forecasting questions and collection dates in the study. The paper does not establish a current leakage rate for news research, legal research, SEO audits or every Google interface.
Use the date filter to find candidates, not certify evidence
A search filter evaluates information available to the retrieval system. Your research question concerns the state of the page at a historical time. Those are different control points. An old URL can now contain a rewritten article, a current sidebar, a new structured-data date or a later event embedded by a script.
Keep the query, filter, interface, signed-in state, language, location, run time and result rank because they describe discovery. Then open a separate evidence record for the page version. Do not let a displayed search date stand in for a preserved document state.
Inspect four leakage paths
| Path | What to inspect | Why it matters |
|---|---|---|
| Updated body | Current paragraphs against the closest pre-cutoff snapshot | A later revision can state the outcome directly. |
| Related module | Recommendations, headlines, navigation and embedded cards | A surrounding link can disclose the resolved event. |
| Unreliable metadata | Visible date, schema, HTTP dates and archive time | A stale or incorrect date can make current content look historical. |
| Absence signal | What a comprehensive current source omits | An omission may narrow the answer even without an explicit statement. |
The paper identifies all four mechanisms. Its absence-based cases were capped below the direct-answer score because silence is easier to overinterpret. Your audit should preserve that restraint.
Score severity before you decide
| Score | Meaning | Corpus action |
|---|---|---|
| 0 | No post-cutoff information, or irrelevant later information | Eligible after ordinary source review |
| 1 | Topical but not informative about the answer | Eligible with a note |
| 2 | Weak directional signal | Qualify or replace |
| 3 | Major signal enabling a strong inference | Exclude unless the passage can be isolated safely |
| 4 | Directly reveals the answer | Exclude and replace with a verified snapshot |
Write the evidence note before the decision. “Updated page” is not enough; identify the exact sentence, module, date conflict or omission that crosses the cutoff. A second reviewer should be able to reproduce the classification without seeing your preferred forecast.
Create one ledger row per result version
The downloadable ledger separates discovery, page identity, archived state, leakage mechanism, review and decision. Use one row for one retrieved URL at one audit time. If a redirect resolves to another URL, preserve both values. If two snapshots are materially different, create two rows rather than overwriting the first judgment.
Never place private queries, account identifiers or licensed page text in a public worksheet. A short evidence note and a permitted snapshot reference are usually enough. Hash a private artifact when you need integrity without redistributing it.
Verify the snapshot, not just the timestamp
- Choose a snapshot captured before the declared cutoff.
- Confirm that the snapshot rendered successfully rather than serving an error, consent wall or incomplete shell.
- Compare body copy, metadata, related modules, media captions and outbound links with the current page.
- Save the snapshot timestamp and the retrieval time separately.
- Record missing resources or scripts that prevent a confident comparison.
An archive timestamp proves that the archive captured something at that time. It does not prove the capture is complete, that the original server supplied the claimed date or that the current search ranking reflects the historical ranking. Keep content eligibility and ranking reconstruction as separate questions.
Treat absence as a qualified signal
Suppose a current timeline covers an event family through 2026 but contains no entry for the outcome you are forecasting. That absence may be informative, yet it depends on an assumption that the timeline is comprehensive and maintained consistently. Record that assumption and cap the severity below a direct statement.
Do not convert “not present” into “did not happen” unless the source owns a complete register and documents its coverage. The same discipline applies to removed products, vanished documentation and expired listings.
Separate retrieval review from outcome review
Have the leakage reviewer judge the document against the cutoff without optimizing for a desired model score. When stakes justify it, conceal the system’s forecast until the page classification is complete. Resolve disagreements against a written rubric and retain excluded rows.
The ACL authors used two annotators on 134 documents to validate their automated judge, reporting 76.1% exact agreement under their combined low-severity treatment and a quadratic weighted kappa of 0.85. That validation supports their audit; it is not a ready-made reliability score for your reviewers.
Run a leak-free sensitivity check
Evaluate once with the proposed corpus and once after removing severity 2–4 material. If the result changes sharply, report both outcomes and make the corpus boundary visible. The paper’s forecasting experiment reported a Brier score of 0.10 with strong-to-direct leakage versus 0.24 with leak-free documents. Lower is better, so leakage made the tested system look substantially more accurate.
Do not transplant that difference into your own expected effect. Your questions, snapshots, model, prompt, period and scoring rule will differ. The useful lesson is procedural: a sensitivity run can reveal whether the conclusion depends on disputed evidence.
Publish the evidence boundary with the result
State the cutoff, retrieval dates, engines, number of questions, number of URLs, snapshot policy, reviewer method and exclusions. Link the worksheet or a privacy-safe aggregate. The small SEO experiment method explains how to preserve baselines and stopping rules, while the evidence-led publishing guide covers claim-level review.
Label any illustrative records as examples. The Batch 10 CSV is a blank operating template, not a SearchEngineAnswer audit result.
Limits of this audit
The ACL study covers Google and DuckDuckGo in a retrospective forecasting setting. It used an LLM judge and forecaster from the same model family, processed long pages selectively and did not experimentally compare archive-based mitigations. The authors disclose those limits. A ledger cannot repair missing snapshots or prove the historical order of search results.
This method reduces one evidence failure: post-cutoff information entering a supposedly historical corpus. It does not validate the truth of a source, remove ordinary selection bias or turn retrospective evaluation into a prospective test.
The release gate
Do not approve a historical corpus until every material result has a recorded cutoff, a reviewed page state and an explicit keep, qualify, exclude or replace decision. Start with the highest-ranked and most outcome-sensitive documents, then expand the audit until the remaining uncertainty cannot change the conclusion.
Primary evidence retrieved August 29, 2026: ACL Anthology paper record, its authoritative PDF and the authors’ public audit repository. More completed method-led work appears in the Research topic archive.
Keep learning
Continue this topic
Next in this topic
AI Overview Click Studies: 1%, 15%, 39.8%
Earlier in this topic
AI Search Source Credibility: Build a 32-Field Audit Ledger
Research
Ask a question or join the discussion