Cloudflare Content Format Chart: What 25 Requests Actually Returned
Two 25-request observations show explicit Markdown negotiation, major byte reductions, cache variation and one documentation URL that later moved.
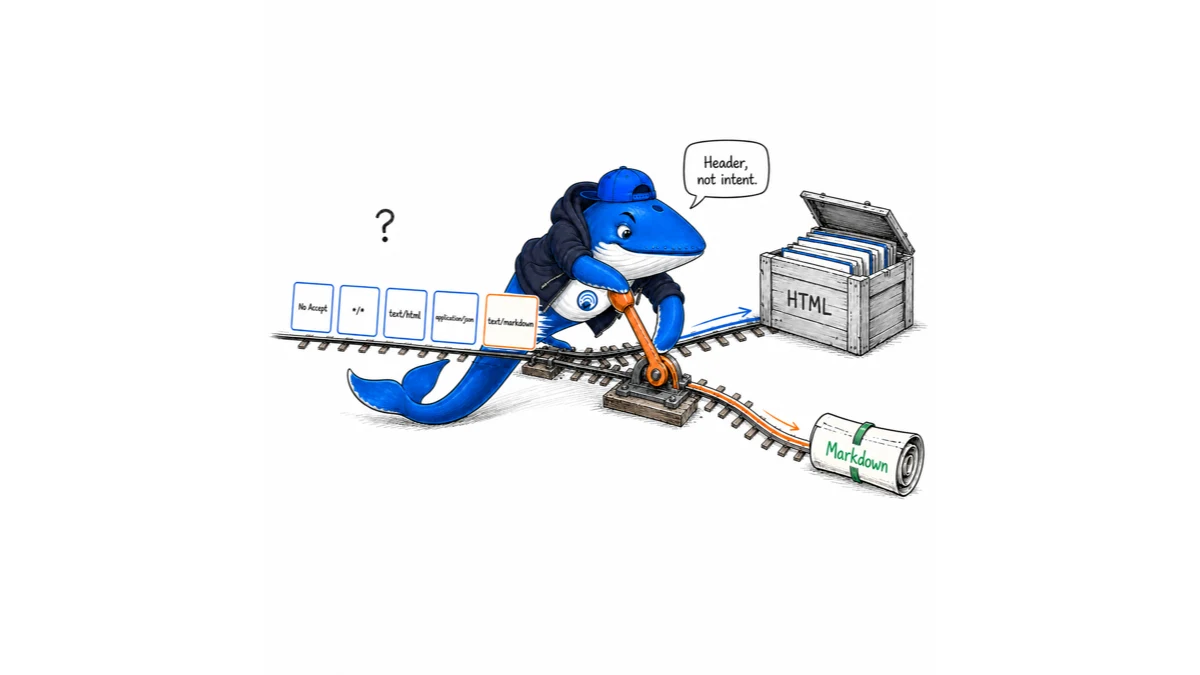
Direct result: we sent 25 controlled HTTP requests to five Cloudflare documentation and blog pages on September 1, 2026 UTC. Only the five requests with an explicit Accept: text/markdown header returned Markdown. The 20 requests with no Accept header, */*, text/html, or application/json all returned HTML.
That result explains what Cloudflare’s Content Format chart can show: a request preference beside the representation that was served. It does not show why a requester selected a header, whether the body was useful, or whether a crawler later indexed, trained on, cited, or referred traffic to the page.
What Cloudflare’s Content Format chart measures
Cloudflare documents three views in AI Crawl Control: a comparison of requested and served content types, a Request Type breakdown based on the request’s Accept header, and a Response Type breakdown based on the response’s Content-Type header. The dashboard can be filtered by date range, crawler, operator, hostname, and path. Cloudflare also documents CSV and image exports that preserve the active filters.
Those fields belong to different sides of an HTTP exchange. Under RFC 9110, an Accept field can influence selection among representations. Content-Type describes the media type of the selected representation in the response. A request and a response can therefore be compared without turning either header into a claim about the client’s motivation.
| Layer | What it records | What it does not prove |
|---|---|---|
| Request Type | The request’s Accept value or category | Why the client asked for it, or what it later did |
| Response Type | The response’s Content-Type | That the body was complete, accurate, parsed, or used |
| Crawler filter | The selected crawler classification within the zone and window | Universal behavior by that operator outside the selected sample |
| Referral metric | A separate observed referral signal where available | Every citation, answer use, or conversion |
Our 25-request observation
We used five public Cloudflare-owned pages: the Markdown for Agents reference, the AI traffic analysis guide, the AI Crawl Control changelog, the Docs for Agents guide, and Cloudflare’s Markdown for Agents announcement. Each page received five GET requests with the same declared Search Engine Answer lab user agent. We did not impersonate GPTBot, ClaudeBot, or another crawler.
The five request variants were: no Accept header, Accept: */*, Accept: text/html, Accept: text/markdown, and Accept: application/json. For every response we preserved the status, response content type, body bytes, content length when present, Cloudflare cache status, Vary, Markdown token headers when present, a SHA-256 body hash, and a UTC retrieval timestamp.
The observation ran from 00:28:29Z through 00:28:38Z on September 1, 2026. It is a negotiation test on pages where Cloudflare has enabled Markdown delivery, not an export of AI crawler activity from the Search Engine Answer zone.
Only the explicit Markdown request returned Markdown
| Request variant | Requests | HTTP 200 | HTML responses | Markdown responses |
|---|---|---|---|---|
No Accept header | 5 | 5 | 5 | 0 |
*/* | 5 | 5 | 5 | 0 |
text/html | 5 | 5 | 5 | 0 |
text/markdown | 5 | 5 | 0 | 5 |
application/json | 5 | 5 | 5 | 0 |
| Total | 25 | 25 | 20 | 5 |
The JSON request is a useful guardrail. It did not make these ordinary pages return JSON; every application/json request received text/html. Likewise, omitting Accept and sending a wildcard did not trigger Markdown. In this fixed sample, the server changed representation only for the explicit Markdown preference.
The Markdown bodies were 84.30% to 97.09% smaller
For each page, we compared the body bytes returned to Accept: text/html with the body bytes returned to Accept: text/markdown. Across all five page pairs, HTML totaled 1,126,074 bytes and Markdown totaled 82,547 bytes;a weighted reduction of 92.67% for this sample.
| Page | HTML bytes | Markdown bytes | Reduction |
|---|---|---|---|
| Markdown for Agents reference | 186,385 | 17,190 | 90.78% |
| Analyze AI traffic | 131,858 | 15,184 | 88.48% |
| AI Crawl Control changelog | 151,904 | 23,849 | 84.30% |
| Docs for Agents | 121,142 | 10,763 | 91.12% |
| Markdown for Agents blog post | 534,785 | 15,561 | 97.09% |
| Five-page total | 1,126,074 | 82,547 | 92.67% |
Cloudflare’s Markdown responses also exposed x-original-tokens and x-markdown-tokens. Those headers totaled 280,928 original tokens and 20,572 Markdown tokens, a 92.68% weighted reduction. The near match with the byte calculation is an observation about these five responses, not a general conversion ratio for other sites or templates.
The same Content-Type did not guarantee the same body
The response hashes revealed a smaller but important result. On every page, the no-Accept request and the explicit text/html request produced the same HTML body hash. The wildcard and application/json requests also matched each other on every page;but their HTML bodies did not match the first pair.
For each of the four documentation pages, the wildcard/JSON HTML body was 353 bytes smaller than the no-header/HTML body. On the blog page, it was 394 bytes smaller. All ten of those responses still declared Content-Type: text/html. We did not isolate which dynamic or request-dependent markup caused the difference, so we do not assign a cause.
This is why a dashboard’s Response Type count is necessary but not sufficient for a parity audit. Two responses can belong to the same media-type bucket while differing at the byte level. Conversely, two bodies with different media types can preserve the same decisive facts. When completeness matters, retain a body hash and sample the fields readers or agents actually need rather than treating the media-type label as a content-quality score.
What the result supports;and what it does not
The test supports a narrow conclusion: Cloudflare’s documented Markdown negotiation worked consistently across five of its own enabled pages, and an explicit Markdown preference was the condition that separated the returned media type in our request matrix. It also confirms why the dashboard must keep Request Type and Response Type separate.
The test does not show that major AI crawlers send Accept: text/markdown, because our own declared client sent every request. It does not show that Markdown improved retrieval, answer quality, citations, rankings, referrals, or conversions. Smaller transport is not automatically more complete evidence: a converted representation can still omit a decisive link, table, caption, structured field, or interactive state.
For real crawler demand, use verified requests from your own zone and follow the AI crawler Markdown header audit. For business outcomes, keep crawler requests separate from the crawl-to-referral ratio and from analytics conversions.
How to audit your own Content Format chart
- Lock the scope. Record the zone, UTC window, hostname, path grouping, plan, and active crawler policy before exporting.
- Export all three views. Preserve Comparison, Request Type, and Response Type with the same filters. Do not compare screenshots taken under different crawler or path selections.
- Verify the requester. Cloudflare documents user-agent filtering and, for Bot Management, verified detection IDs. A user-agent string alone can be spoofed.
- Keep status families visible. A blocked, challenged, redirected, or failed request is not equivalent to a successful origin representation.
- Sample body parity. For approved public paths, compare facts, links, headings, tables, author and date signals, image alternatives, canonical hints, and structured data across returned formats.
- Measure downstream outcomes separately. Citation, referral, engagement, conversion, and revenue each need their own denominator and observation window.
Cloudflare’s GraphQL guide documents filters for real client traffic, paths, status ranges, user agents, referrer hosts, and detection IDs where available. Those fields can add operational context, but they do not convert a content-format count into proof of search or model use.
Read the chart as a negotiation matrix, not a leaderboard
A large bar under one request type does not establish that the format is preferred by every crawler. First ask which crawlers, paths, hostnames, statuses, and dates are inside the filtered count. Then compare the requested and served sides as a matrix: Markdown requested and Markdown served; Markdown requested and HTML served; HTML requested and HTML served; or another request type mapped to another representation.
The mismatches are often more actionable than the largest bar. A Markdown request that receives HTML may point to an ineligible page, disabled conversion, a non-HTML origin response, a policy rule, a cache path, or another implementation condition. An HTML request that receives Markdown would deserve a separate cache and negotiation check. A failed or blocked request may never yield the successful representation implied by an origin-only comparison.
Keep the denominator explicit for each cell. “80% Markdown” is ambiguous unless the reader knows whether that means 80% of all requests, 80% of successful responses, 80% of one verified crawler’s requests, or 80% of one path cohort. Exported counts, filters, and timestamps make the statement auditable.
Inspect the 25-response evidence
Open the accessible observation sheet for the result summary, field definitions, and page-level size comparison. Download the raw 25-row CSV for request variants, response headers, body sizes, hashes, and timestamps.
The raw response bodies and headers remain in the private editorial package. They are retained for verification but are not republished wholesale because they reproduce Cloudflare page content. The CSV records hashes and response metadata needed to verify the run without distributing complete copies.
Response interpretation
Twenty-five requests produced outcomes that needed more than a success/fail label
Content negotiation and edge behavior can change what a client receives without changing the public URL.
- Status
- Was the response successful, redirected, blocked or rate limited?
- Representation
- Which content type and encoding were returned?
- Body
- Did the bytes contain the expected human-readable or machine-readable material?
- Repeat
- Did a controlled second request reproduce the same result?
My takeaway: My decision rule is to preserve headers and body hashes together. A chart without the underlying response evidence is too easy to misread.
Sources, method, and limitations
- Cloudflare: Analyze AI traffic ; Content Format views, filters, and export behavior.
- Cloudflare: Markdown for Agents ; negotiation behavior, response headers, output structure, availability, and limits.
- Cloudflare: AI Crawl Control GraphQL API ; documented filters and crawler analytics examples.
- RFC 9110: HTTP Semantics ; representation metadata,
Content-Type,Accept, and content negotiation.
Retrieval dates were August 31, 2026 in America/Los_Angeles and September 1, 2026 UTC. The direct test covered five Cloudflare-owned pages during a nine-second window from one client and network location. Dynamic page elements can change byte counts, and Cloudflare can revise its documentation or edge behavior. Re-run the supplied method before treating these values as current. Most importantly, do not generalize our client’s five header choices into a claim about any named crawler.
September 23 recheck: the negotiation pattern held on four live pages
We repeated the same five-request matrix against five Cloudflare URLs at 08:19 UTC on September 23, 2026. Four URLs were live, producing 20 successful responses. The former Content Signals documentation URL returned HTTP 404 in all five variants, so we excluded it from the format comparison and preserved the failure in the public method record.
On every live page, no Accept header, */*, text/html and application/json returned HTML. Only Accept: text/markdown returned text/markdown; charset=utf-8. This matches the earlier observation: the server negotiated a representation from the request, while the URL remained unchanged.
The four explicit HTML responses totaled 4,791,680 bytes. Their Markdown counterparts totaled 65,584 bytes, a 98.63% byte reduction in this capture. That number is descriptive, not a universal compression forecast. One new blog page contributed 3.30 MB of HTML, so the weighted result is sensitive to page choice and current site assets.
The cache headers now reveal the implementation boundary
The four Markdown responses included Vary: accept alongside accept-encoding and returned CF-Cache-Status: HIT. HTML responses varied on encoding only. Cloudflare’s new Vary Cache Rules explain why this matters: an origin can declare the request headers that change a representation, while a cache rule decides whether to normalize, pass through or bypass that variation.
Do not assume that two visible formats produce only two cache keys. Cloudflare warns that raw Accept and Accept-Language combinations can multiply through value order, missing headers and values that normalize to empty. Test the exact request variants a client sends, use the same client when comparing CF-Cache-Status, and verify that a Markdown hit never serves HTML or vice versa.
What changed in our recommendation
The earlier recommendation to test Accept before assuming Markdown support still stands. We now add a cache requirement: log Vary, CF-Cache-Status and a body hash for every variant. Format negotiation without cache isolation can create a correctness problem even when both representations are valid.
The 25 raw response headers and bodies are retained in the September 23 research package. The dead documentation URL is reported rather than silently replaced, preserving comparability with the earlier run. See Cloudflare’s Vary support announcement for the rule behavior and our crawler Accept-header test for a smaller protocol you can run on your own server.
Keep learning
Continue this topic
Next in this topic
2026 Retrieval-Augmented Answer Patents: 64 Claims-First Families
Earlier in this topic
Mistral Search Toolkit: Build a 32-Field Retrieval Release Gate
Research
Ask a question or join the discussion