ChatGPT Plugin Metadata: Test Tool Selection and Restraint
Evaluate plugin metadata with direct, indirect, and negative prompts; confusion counts; argument and safety checks; controlled revisions; and a reusable ledger.
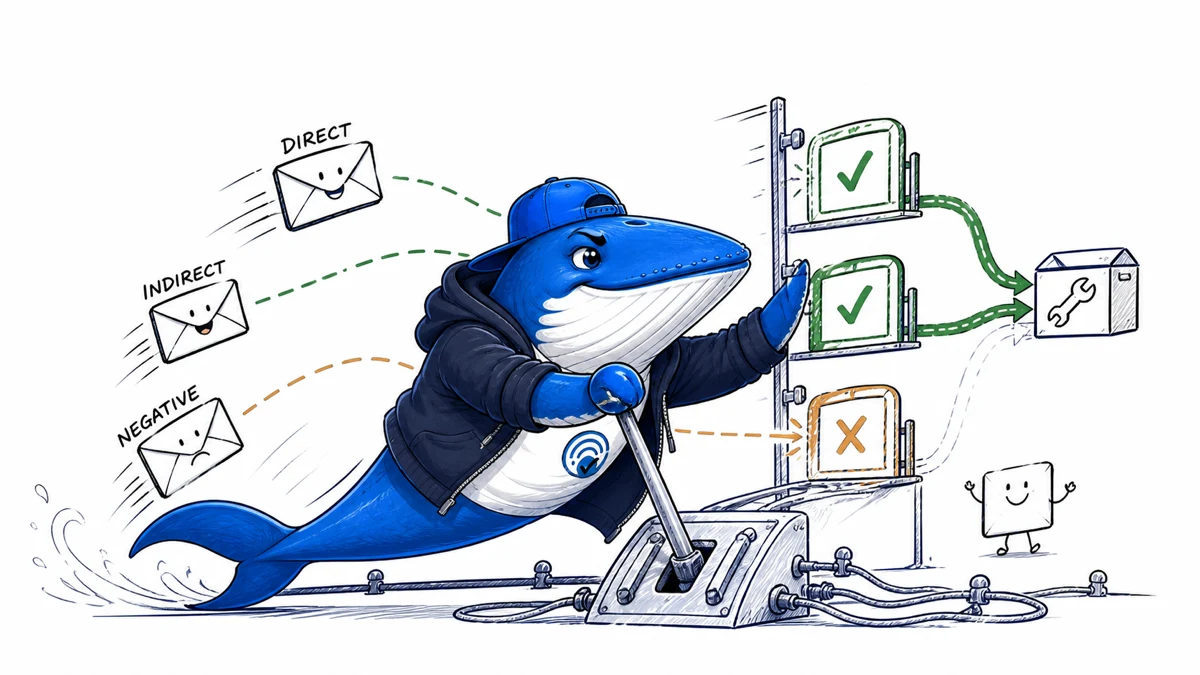
Direct answer: ChatGPT plugin metadata is a tool-selection contract. Names, descriptions, parameter documentation, and safety annotations help ChatGPT and Codex decide when a tool is relevant, what arguments to pass, and when to abstain. The defensible optimization target is correct invocation and restraint—not a search ranking, citation share, installation guarantee, or generic “AI visibility” score.
OpenAI’s current plugin documentation recommends a labelled golden-prompt set with direct, indirect, and negative cases. It also recommends evaluating the complete set in developer mode, changing one field at a time, preserving revisions, and prioritizing precision on negative prompts before chasing marginal recall.
The reader job: improve selection without increasing harmful calls
This guide is for a product or content team that has an MCP-backed plugin whose tools are missed, confused with neighboring tools, or invoked when the user wanted something else. The task is not to make every description broader. It is to make the intended and disallowed cases legible enough to test.
Keep the stable URL of this article even as product terminology evolves. In the current official documentation, “plugin” is the package, while ChatGPT and Codex select individual tools using their metadata.
Treat metadata as a classification contract
A useful tool description answers four questions: what outcome the tool produces, when it should be used, when it should not be used, and what state it may change. Avoid slogans such as “the best calendar assistant.” They consume space without separating the tool from alternatives.
| Field | What to express | Failure to count |
|---|---|---|
| Name | Domain plus action, such as calendar.create_event |
Wrong neighboring tool selected |
| Description | Intended situation and important disallowed cases | Missed relevant call or accidental activation |
| Parameters | Meaning, examples, required values, and constraints | Guessed, invalid, or incomplete argument |
| Read-only hint | Whether the tool only retrieves or computes | Incorrect confirmation or permission path |
| Other safety hints | Whether non-read actions are destructive or open-world | Side effect represented inaccurately |
Start with the documented metadata rules
OpenAI advises pairing the domain with the action in a tool name, starting descriptions with “Use this when…,” naming disallowed cases, documenting parameters with examples and allowed values, and setting readOnlyHint: true only for tools that never create, update, delete, or send data outside the conversation. For non-read-only tools, the documentation also describes destructive and open-world hints.
Those annotations are declarations, not marketing levers. Do not label a mutating tool read-only to reduce friction. Incorrect safety metadata can route the user through the wrong approval path and invalidate an otherwise good selection score.
Build a golden prompt set before rewriting
Create labelled examples from real user language and known failure modes. Direct prompts name the product or data source. Indirect prompts name the desired outcome without naming the tool. Negative prompts are cases in which another tool, a built-in capability, or no action is the better response.
| Class | Count | Expected behavior | Primary metric |
|---|---|---|---|
| Direct | 20 | Select the named tool when the request is supported | Recall and argument accuracy |
| Indirect | 20 | Recognize the outcome without overgeneralizing | Recall and neighboring-tool confusion |
| Negative | 20 | Abstain or select the appropriate alternative | False activations and correct restraint |
Sixty is an editorial starter, not an OpenAI benchmark. Expand it when tools, intents, locales, or side effects differ materially. Every row in the downloadable metadata evaluation ledger is marked EXAMPLE-REMOVE; delete the examples before using it.
Label the expected outcome precisely
“Should work” is not a test label. Specify the expected tool, expected abstention or alternative, required arguments, optional arguments, permission boundary, and completion evidence. Add an acceptable-clarification state when the user has not supplied information that should not be guessed.
For a destructive or open-world action, distinguish selection from execution. The right tool may be selected while the correct outcome is to request confirmation rather than perform the action.
Use a confusion matrix, not one average
With 40 prompts that expect the tool and 20 negatives, four missed relevant calls yield 90% recall in this simplified fixture. One mistaken call among 20 negatives yields a 5% negative false-activation rate. Do not call that “95% precision” unless the denominator and formula are stated; ordinary precision uses true positive calls divided by all calls predicted for the tool.
| Outcome | Count when | Why it matters |
|---|---|---|
| True positive | The intended tool was correctly selected | Supports tool-level precision and recall |
| False positive | The tool ran when it should not | Measures accidental activation |
| False negative | The tool was expected but not selected | Measures missed opportunities |
| Wrong tool | A neighboring tool was selected | Reveals taxonomy or wording overlap |
| Argument failure | Selection was right but inputs were wrong | Separates description from schema problems |
| Execution failure | Tool call failed after correct selection | Prevents operational defects from becoming metadata claims |
Evaluate in a controlled environment
OpenAI’s guidance directs developers to register the MCP server in ChatGPT developer mode, run the golden set, and record the selected tool, arguments, and whether the component rendered. Capture the client, model setting where visible, plugin version, server version, fixture version, date, and run number. Product behavior can change; an unversioned result is difficult to reproduce.
Test the same fixture in Codex only if Codex is a supported target. Do not merge ChatGPT and Codex results into one score. The official page names both as tool-selection consumers, but each environment should retain its own rows.
Change one metadata field at a time
Freeze a baseline, edit one name, description, parameter document, or annotation, and replay the full fixture. Record a diff and a reason for the change before seeing the outcome. If multiple fields move together, the result cannot identify which change improved or damaged selection.
Keep regressions visible. A description that improves indirect recall can increase negative false activations. Use a release gate that requires acceptable restraint, argument accuracy, and side-effect handling—not just more calls.
Test neighboring tools as a set
Many selection failures are taxonomy failures. If calendar.search_events, calendar.create_event, and reminders.create share vague descriptions, editing only one can move mistakes elsewhere. Create contrast prompts that differ by one intent, object, or side-effect boundary.
Use the AI visibility measurement crosswalk to keep this invocation layer distinct from web discovery and citation layers.
Monitor drift after release
OpenAI recommends reviewing tool-call analytics, capturing feedback, and replaying prompts periodically—especially after adding tools or changing fields. Add the metadata revision and fixture version to every incident. A spike in wrong-tool confirmations may come from a new neighbor, a changed user vocabulary, or a platform update.
Do not collect sensitive prompt content merely to improve selection. Minimize, redact, aggregate, and retain data under the product’s privacy and security requirements.
Separate plugin optimization from web AEO
Plugin invocation happens inside a tool-selection system. Web AEO concerns crawl access, retrieval, citation, answer use, referrals, and outcomes across web sources. The systems can influence the same business, but their units are different. A plugin team reports calls, restraint, arguments, completion, side effects, and user correction. A publisher reports visibility observations, citations, absorption, visits, and outcomes.
The AEO guide covers the web-publisher layer. Combining both layers into one visibility score obscures the cause of a change.
A defensible release gate
- All fixture rows have a reviewer-approved expected outcome.
- No unreviewed false activation can create, delete, overwrite, purchase, publish, or send.
- Argument accuracy is reported separately from selection.
- Negative cases meet the declared restraint threshold.
- Every metadata revision has a diff, owner, date, and rollback point.
- The complete fixture is replayed in each supported client.
Primary documentation and boundary
The source is OpenAI’s current Optimize Metadata guide. It states that ChatGPT and Codex use tool metadata, defines direct, indirect, and negative golden prompts, documents the naming and annotation guidance, and recommends methodical iteration and production monitoring.
This article adds the 60-prompt example, detailed outcome ledger, confusion-matrix cautions, release gate, and cross-environment separation. Those are Search Engine Answer’s proposed operating method, not official OpenAI thresholds.
Keep learning
Continue this topic
Next in this topic
ChatGPT Ads Pixel vs Conversions API: What Each One Measures
Earlier in this topic
AI Visibility Tools in 2026: A Buyer’s Measurement Matrix
Tools & Workflows
Ask a question or join the discussion