Claude Inference Hooks: A Shadow-to-Enforce Release Gate
Deploy Claude inference hooks with signed-request verification, shadow review, explicit verdicts, tested failure modes, latency thresholds, incident ownership and rollback.
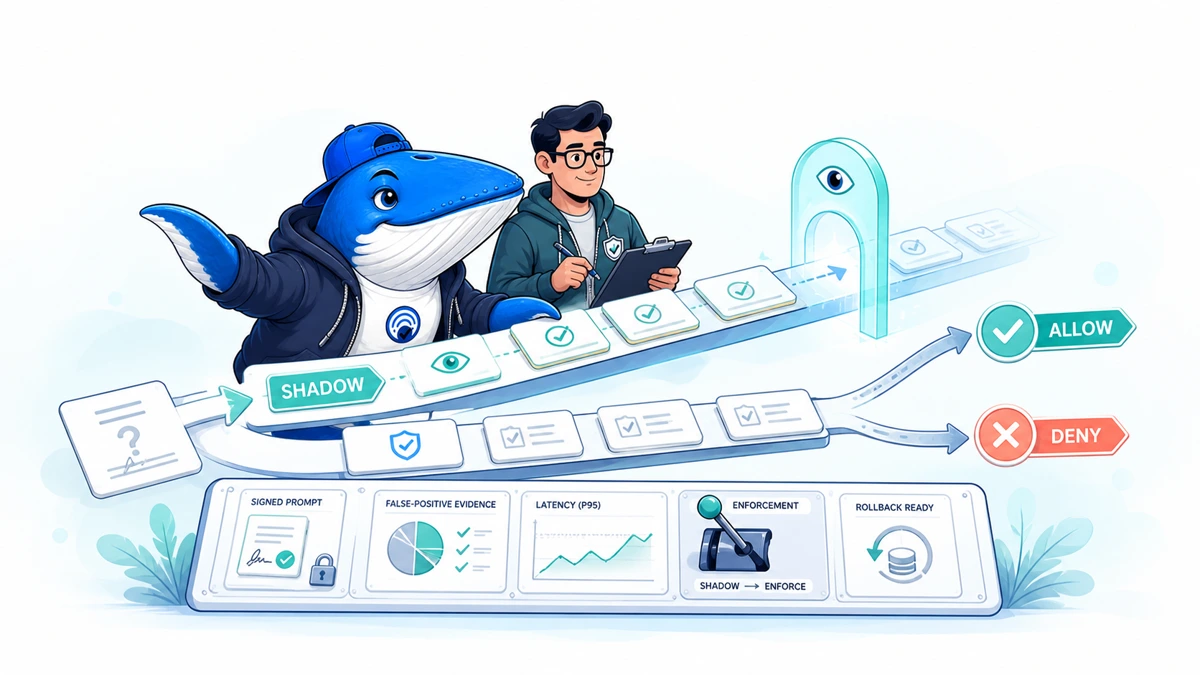
Direct answer: treat Claude inference hooks as a release gate, not as a keyword blocklist. Start in shadow mode, verify signed requests, return an explicit allow or deny decision with HTTP 200, test both failure policies, and move to enforcement only after false positives, latency, duplicate delivery and incident ownership meet written thresholds.
The reusable control is a versioned decision record that joins the request, policy version, verdict, reason, failure path and human owner. Download our Claude inference-hook release-gate ledger (CSV). It contains one clearly marked example row; remove it before recording production events.
What the hook controls—and what it does not
Anthropic documents inference hooks as a beta control for Claude Enterprise organizations. A governed prompt is sent to an organization-controlled HTTPS endpoint before inference; the endpoint returns an allow or deny decision. The current hook event is the prompt. It is not a response scanner, a factuality checker or proof that an approved answer is safe to publish.
The control applies to supported Claude Enterprise surfaces described by Anthropic, including claude.ai, Cowork and Claude Code. Anthropic says Platform API organizations and third-party deployments such as Amazon Bedrock and Google Cloud are outside this hook path. Map the real traffic surface before claiming organization-wide coverage.
Use three gates, not one switch
| Stage | User effect | Evidence to collect | Exit condition |
|---|---|---|---|
| Off | No hook decision | Inventory of surfaces, data classes and owners | Endpoint, policy and incident plan approved |
| Shadow | Requests continue regardless of simulated verdict | Would-deny rate, false positives, latency, payload size and failures | Written quality and reliability thresholds met |
| Enforcing | Deny verdicts block governed prompts | Denied events, user feedback, exceptions, failures and rollback signals | Ongoing review; rollback if thresholds break |
Shadow mode is useful only when its decisions are reviewed. Sampling only successful allows hides the cost of mistaken denials. Review all high-severity matches, a stratified sample of allows, and every failure-path event.
Build against the request contract
The endpoint specification says the webhook is a signed POST and can include the conversation transcript, extracted attachment text, tool calls and tool results. It does not include raw image or file bytes, system prompts, tool definitions or Anthropic internal context. A classifier that requires absent data must return an explicit indeterminate state; it must not pretend the data was inspected.
Transcripts can be several megabytes. Raise and test request-size limits deliberately, stream or bound parsing where possible, and reject malformed input without logging the full transcript. Treat source.application as advisory context, not as an authorization boundary.
Verify first, parse second
- Accept traffic only on a public HTTPS endpoint on port 443; Anthropic says redirects and reverse tunnels are unsupported.
- Read the raw request bytes needed for signature verification before JSON normalization changes them.
- Validate the signature and freshness according to Anthropic’s documented webhook scheme.
- Reject replayed or duplicate events using the webhook ID or request ID.
- Only then parse the event and send the minimum fields to the policy engine.
Authentication proves that a request is from the expected sender. It does not prove the prompt is permissible. Signature verification and policy evaluation belong in separate log fields and separate alerts.
Return an unambiguous verdict
Anthropic requires HTTP 200 for both allow and deny decisions; a non-200 response is a webhook failure, not a denial. Keep the transport result, parser result and policy verdict separate. Validate the response body against a strict internal schema before returning it.
| Field | Purpose | Guardrail |
|---|---|---|
| request_id / webhook_id | Deduplication and incident lookup | Never use prompt text as the identifier |
| policy_version | Reproduce the rule set | Immutable version, not “latest” |
| verdict | Allow or deny | No silent default |
| deny_reason | User-facing correction path | Anthropic caps it at 500 characters |
| reference_id | Support and Activity Feed join | At most 50 characters; no personal data |
| failure_mode | Fail-open or fail-closed path | Record the active configuration |
Write denials for recovery
A denial should say what policy category matched, what the user can change, and where to request an exception. Do not echo secrets, private source passages or classifier internals. A useful pattern is: “Blocked by policy P-17: unpublished customer identifiers. Remove the identifiers or use the approved redaction workflow. Reference: HK-0241.”
A generic “policy violation” creates support load and encourages repeated guessing. An over-detailed denial can disclose sensitive rules. Test messages with editors, security reviewers and accessibility users before enforcement.
Choose fail-open or fail-closed by data class
Anthropic’s configuration guide supports allowing or blocking requests when the hook fails. One global choice is easy to operate but can be too blunt. If the product configuration is global, route high-risk work to a separate governed workflow or prohibit it until the reliability target is proven.
| Work class | Preferred failure posture | Reason | Compensating control |
|---|---|---|---|
| Public brainstorming | Often fail-open | Low confidentiality; continuity matters | Post-use sampling and bounded tools |
| Unpublished editorial drafts | Depends on source sensitivity | Business impact varies | Redaction and approved workspaces |
| Regulated or customer data | Usually fail-closed | Disclosure cost outweighs interruption | Alternate approved workflow and incident owner |
These are design defaults, not legal conclusions. Security, privacy and legal owners should approve the actual classifications.
Set a latency and availability budget
The hook sits before inference, so its time is added to the user’s wait. Measure median, p95 and p99 decision latency, timeouts, DNS/TLS failures, non-200 responses and malformed verdicts. Include cold starts and large transcripts. A fast median can hide a damaging long tail.
Define a rollback signal before enforcement—for example, a sustained timeout rate, p99 latency ceiling or mistaken-denial rate. The rollback action should change the enforcement state without deleting the evidence needed to diagnose the event.
A release test you can run
- Create a frozen set of allowed, denied, ambiguous, oversized, malformed, duplicate and replayed requests.
- Include attachments and tool traces represented exactly as the hook sends them.
- Run every fixture against a pinned policy and service version.
- Have two reviewers label a blinded sample; adjudicate disagreements.
- Measure false-deny and false-allow rates by severity, not only overall accuracy.
- Inject timeouts, invalid signatures, non-200 responses and malformed JSON.
- Verify the configured fail-open or fail-closed result on the Claude surface.
- Move to a limited enforcing cohort with an on-call owner and rollback command.
The release ledger links each acceptance rule to evidence. It also prevents a later policy edit from being credited to an older test.
Define acceptance criteria before reviewing results
Use thresholds that reflect harm. A team might require zero false allows for a small set of critical secrets, an agreed upper bound for false denials in ordinary editorial work, a p99 latency ceiling, successful duplicate handling and demonstrated rollback. The exact numbers belong to the organization; publishing them after the test turns a gate into a story.
The Managed Agents run-control method applies the same principle to cost: the authoritative event and the human decision must stay joinable. For evidence quality after a request is allowed, use the evidence-led publishing guide; the hook itself does not validate sources.
Review denied events without storing everything
Anthropic says the reference ID can help join a denial to the Activity Feed. Store the minimal operational record: event ID, timestamps, surface, policy version, verdict category, reference ID, latency, failure path and reviewer outcome. Keep sensitive transcripts in the approved system of record, with retention and access controls—not in a convenience dashboard.
Audit exceptions as policy changes. Record requester, approver, duration, scope and compensating controls. Expire them automatically; permanent exceptions should require a new policy version.
Implementation checklist
- Map covered and uncovered Claude surfaces.
- Assign endpoint, policy, privacy and incident owners.
- Verify signatures over raw bytes and reject replays.
- Handle multi-megabyte transcripts and unknown future fields.
- Return HTTP 200 for both valid verdicts.
- Keep user-facing reasons concise and non-sensitive.
- Test both the verdict path and configured failure path.
- Run shadow review before enforcement.
- Version policy, fixtures, deployment and rollback evidence.
Sources, method and limits
Sources: Anthropic’s inference-hooks overview, endpoint specification and configuration documentation, retrieved August 31, 2026.
Method: We converted the documented transport, enforcement and failure contracts into a release sequence, audit schema and acceptance test. The CSV is a blank operational template with one example row, not a record of Search Engine Answer production traffic.
Limits: Search Engine Answer has not deployed an inference hook and has not measured Anthropic’s service in production. Inference hooks are beta; supported surfaces, schemas and limits can change. Recheck the official documentation and your Claude admin interface before enforcement.
Keep learning
Continue this topic
Next in this topic
Claude Managed Agents Budgets: A Research Run-Control Method
Earlier in this topic
Gemini API Key Migration: Build a 30-Field Cutover Register
Tools & Workflows
Ask a question or join the discussion