Anthropic Traced 8,913 AI-Written Articles to 70 Fake News Sites
Anthropic documented a coordinated network of fabricated news sites, paired social accounts and rigid publishing constraints. The useful lesson is the network footprint, not a guess about whether one paragraph sounds AI-written.
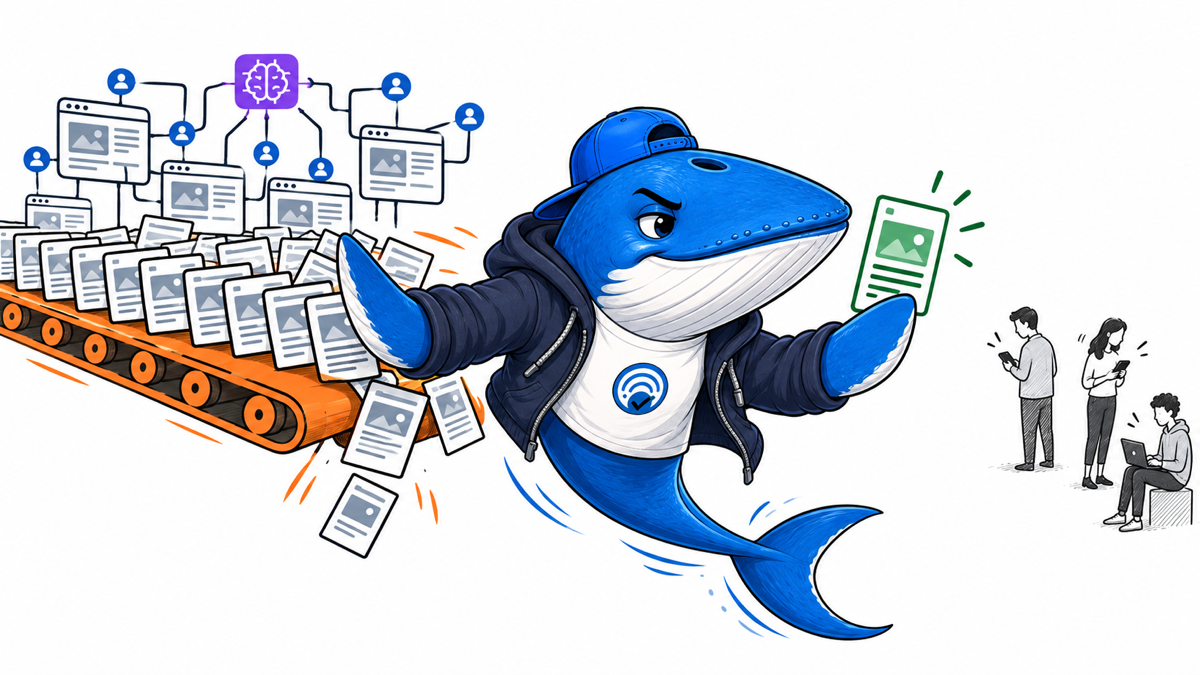
Anthropic says one commercial influence operation produced at least 8,913 articles across approximately 70 fabricated news sites. The network also used 70 paired X accounts, more than 250 inauthentic commenting accounts and content in about 20 languages.
The revealing part is not that AI wrote many articles. It is the operational footprint: a ten-week registration burst, one shared deployment, rigid output instructions, repeated internal-link quotas, fabricated bylines and synchronized distribution. Anthropic found little observable authentic engagement despite the production scale.
The network was large, but its shape is more useful than the headline number
Anthropic’s September threat-intelligence report describes a disrupted commercial operation that built a synthetic publishing system across six continents. Its output included at least 8,913 articles in roughly 20 languages. One country-focused slice contained 318 articles about the Democratic Republic of the Congo.
Raw article count can be misleading because a legitimate publisher can also operate at scale. The more discriminating evidence comes from the combination of infrastructure, production rules and distribution behavior. Anthropic reports that the sites were registered within a ten-week window and deployed through a shared technical setup. The publication pipeline asked for fixed JSON, formatted HTML, exact character limits and three to four internal links per article.
Those constraints turn a vague suspicion about “AI content” into an inspectable system. The content was not simply generated quickly. It was generated to fit a repeatable publishing contract across a network of supposedly independent properties.
A newsroom label hid a production line
A real newsroom can reuse templates, content systems and editorial standards without being deceptive. The warning appears when repeated implementation details combine with false independence and fabricated provenance.
| Observed artifact | What it can support | What it cannot prove alone |
|---|---|---|
| About 70 domains registered in a ten-week burst | Coordinated infrastructure timing | That every recently registered publisher is deceptive |
| One shared deployment | Common technical operation | Common ownership without corroborating records |
| Fixed JSON, HTML and character limits | Standardized generation workflow | That structured output is inherently abusive |
| Three to four internal links per article | A repeated site-authority tactic | That ordinary internal linking is manipulation |
| Fabricated bylines and paired social accounts | False editorial identity and coordinated distribution | That all pseudonymous writing is inauthentic |
| Little observable authentic engagement | Production volume did not become broad audience response | Complete absence of unseen readers or impact |
The important diagnostic is the intersection. A single signal may have an innocent explanation. A tight registration window, shared deployment, identical output constraints, false bylines, matched social accounts and synchronized publication provide a much stronger basis for investigation.
The operation explicitly targeted search authority
Anthropic says the articles were designed to increase the sites’ authority rankings on search engines. The repeated internal-link requirement matters because it shows that the links were part of the production specification, not an occasional editorial decision.
That does not tell us whether any search engine rewarded the network. Anthropic did not publish Search Console data, ranking histories, crawl logs or a Google enforcement notice. The supported statement is about the operator’s apparent objective and workflow. A ranking outcome remains unproven.
This distinction should change how publishers discuss scaled AI content. “The content was produced to manipulate authority” is an evidence-backed description of intent in this incident. “Google ranked thousands of fake articles” would require ranking evidence that the report does not provide.
Google’s policy focuses on purpose and user value, not the tool alone
Google defines scaled content abuse as creating many pages primarily to manipulate rankings rather than help users. The policy applies regardless of whether the pages are made by automation, people or a mixture of both.
Google’s examples include generating many pages with AI without adding value, scraping or transforming material, creating multiple sites to hide the scale of a campaign and producing pages around search queries that make little sense to readers. The network Anthropic describes overlaps with several of those risk patterns, but a policy comparison is not a finding that Google took action against these specific sites.
For a legitimate publisher, the practical test is not “Did an AI system touch this draft?” It is whether the page exists to resolve a reader’s problem with identifiable authorship, defensible evidence, original judgment and accountable correction. Repeating a house style is normal. Repeating a false identity and a search-manipulation contract is not.
Synchronized timing can expose coordinated distribution
Anthropic reports coordinated publication activity occurring within three minutes. Timing is useful because it connects content production to distribution behavior. A network that presents itself as many independent outlets becomes harder to explain when matching properties publish or amplify related material almost simultaneously.
A responsible audit should preserve timestamps in UTC, canonical URLs, author names, social-account identifiers, link targets and archive copies. It should also compare ordinary publishing cadence before labeling a burst suspicious. A wire service, emergency update or planned campaign can produce legitimate synchronization. The case grows stronger when tight timing appears beside shared infrastructure and false identities.
A six-part audit can separate scale from coordination
- Group domains by registration window. Record registrar dates and confidence in the ownership connection. Do not equate recent registration with misconduct.
- Compare deployment fingerprints. Look for shared templates, asset paths, analytics identifiers, hosting patterns and build artifacts. Preserve the raw observation before assigning ownership.
- Sample the output contract. Measure repeated character bands, markup order, heading patterns and internal-link counts across a defined article sample.
- Verify authorship. Check whether bylines have stable biographies, histories, corrections and traceable expertise. Avoid treating a missing social profile as proof of fabrication.
- Map distribution timing. Compare publication and social amplification in a common timezone. Report the threshold used for “synchronized.”
- Separate produced, indexed, ranked and engaged. Count those states independently. A published page is not necessarily crawled, an indexed page is not necessarily visible, and visibility is not authentic readership.
This sequence creates a falsifiable record. An operator can explain shared infrastructure, a network can show independent authorship, or traffic data can contradict the assumption that no audience existed. The goal is to test coordination, not to build a detector that flags every efficient publisher.
The operation’s weak result is part of the finding
Anthropic classified the case as Category Two and reported no evidence that it broke out beyond its own network activity. It also observed little authentic engagement. That outcome matters because it challenges the assumption that more pages, languages and accounts automatically create influence.
The network appears to have solved the production problem more successfully than the trust problem. Thousands of articles can manufacture surface area, but they cannot guarantee attention, credibility, citation or durable search demand. The same lesson applies to ordinary publishing: output is an input metric. Reader response and useful outcomes are separate measures.
For SearchEngineAnswer’s own editorial decisions, this is a reason to consolidate small announcements rather than multiply pages. A stronger article should add primary evidence, a repeatable check, a worked example or a judgment that helps the reader act. Page count is not topical authority.
What legitimate publishers should document now
A publisher using AI assistance can make the opposite footprint visible:
- stable author and organization identities;
- links to primary evidence rather than recycled summaries;
- clear separation between reporting, inference and opinion;
- article-specific examples, tests or records;
- meaningful updates and correction history;
- internal links chosen for reader continuation, not a fixed quota;
- publication volume that editorial review can realistically support.
Our evidence-led publishing guide covers claim sourcing and maintenance. The AI citation failure audit shows why retrieval, exposure, attribution and validation should remain separate. The SearchEngineAnswer build log documents the same principle on this site: authority has to be earned through inspectable work, not asserted through volume.
The useful warning is operational, not anti-AI
This incident does not show that AI-assisted publishing is inherently low value. It shows how automation can industrialize deceptive identity, coordinated distribution and ranking manipulation when those goals are built into the production system.
The strongest signals live outside the prose itself. Registration timing, shared deployment, output constraints, byline authenticity, link quotas, paired accounts, synchronization and real engagement create a more reliable picture than a classifier guessing whether one paragraph sounds machine-written.
Anthropic’s report provides evidence of the network’s scale and coordination. Google’s policy provides the public rule boundary. Neither source proves a Google ranking benefit or enforcement action. That narrower conclusion is also the more useful one.
Primary records
Keep learning
Continue this topic
Next in this topic
Baidu and Google Gave Similar AI Answers From Different Source Webs
Earlier in this topic
Google Tests ‘Dive Deeper’ Overviews Inside Discover Video Cards
AEO & AI Search
Ask a question or join the discussion